Part of Language AI Handbook
Examines gating networks in MoE architectures. Topics include router design, softmax gating, Top-K selection, training dynamics.
Choose your expertise level to adjust how many terms are explained. Beginners see more tooltips, experts see fewer to maintain reading flow. Hover over underlined terms for instant definitions.
Article links
Make inline references clickable
Gating Networks
In the previous chapter, we explored how expert networks give specialized computational pathways within a Mixture of Experts (MoE) architecture. But having multiple experts raises an immediate question: how does the model decide which expert to use for each input? This decision falls to the gating network, also called the router, which is the traffic controller directing tokens to appropriate experts.
The router might seem like a minor component (often just a single linear layer), but its design affects model quality and training stability. A poorly designed router can cause expert collapse (where only one expert gets used), severe load imbalance, or failure to learn specialization. Getting the router right is one of the central challenges in MoE systems.
This chapter examines how routers work: their architecture, how they compute routing scores, how they learn through backpropagation, and what behavioral patterns emerge during training. Understanding the router gives the basis for the routing strategies and balancing techniques we'll explore in upcoming chapters.
Router Architecture
The gating network in modern MoE transformers is remarkably simple: a linear projection from the token representation to a score for each expert. Despite this simplicity, the router must learn to make complex decisions about which experts are best suited for each input. To understand why this seemingly minimal architecture succeeds, we need to examine both its mathematical structure and the reasoning behind key design choices.
The Linear Router
At the heart of every MoE layer lies a deceptively simple question: given a token's representation, which expert should handle it? The standard router architecture answers this question with a single linear layer without bias. Before we write down the formula, consider what we need: a way to transform each token's high-dimensional representation into a set of scores, one for each expert. These scores should capture how well-suited each expert is for processing that particular token. A linear projection accomplishes exactly this:
where:
- : the vector of raw routing scores (logits) for the experts
- : the input token representation vector of dimension
- : the learnable router weight matrix of dimension
- : the number of experts
This formula performs a matrix multiplication that projects the -dimensional token representation onto scores, one for each expert. The result is a vector of routing logits that will later be converted to probabilities.
This design choice, a simple linear projection, might seem limiting at first glance. After all, modern deep learning has shown the power of multi-layer networks for capturing complex patterns. Why not use a more expressive multi-layer network for routing? Several factors favor the linear design:
- Computational efficiency: The router runs for every token, so it must be fast. A linear layer adds minimal overhead compared to the expert computations themselves.
- Sufficient expressivity: The input representation already encodes rich semantic information from prior layers. By the time a token reaches the MoE layer, attention mechanisms have already captured contextual relationships. The router just needs to project this pre-processed information to expert preferences.
- Training stability: Simpler architectures are easier to train and less prone to the instabilities that plague MoE systems. Adding nonlinearities to the router can create optimization challenges.
- Interpretability: Linear routers allow clearer analysis of what input features influence routing decisions, since the mapping from input dimensions to expert scores is direct.
Input Representation
What exactly feeds into the router? Understanding the input is important because it determines what information the router can use to make its decisions. In a transformer's MoE layer, the router typically receives the same input that would go to a standard FFN block. This is the output of the attention sublayer (plus residual connection and normalization):
- : the input vector to the router
- : the input state from the previous layer
- : the output of the self-attention mechanism
- : the normalization operation that stabilizes the representation
This formula shows that the router's input incorporates both the attention output and the original hidden state through the residual connection, all normalized for stable computation. This representation already captures contextual information about the token's role in the sequence. The attention mechanism has allowed the token to gather needed information from other positions, so the router is not making decisions based on the token in isolation. Instead, the router's job is to translate this contextual representation into expert preferences.
Some architectures experiment with alternative inputs. For instance, some routers use the pre-normalization representation or concatenate multiple representations to give richer information. However, the standard approach (using the same input as the FFN) remains dominant due to its simplicity and effectiveness. Using the same input also ensures consistency: the expert receives the same representation that was used to decide to route to it.
Router Weight Matrix
Understanding the router weight matrix , the only learnable component, gives intuition about how routing decisions are made. Each column of the matrix is a "prototype" for expert . You can think of these prototypes as characteristic patterns that expert is designed to handle. The routing score for expert is in effect the dot product between the input and that expert's prototype:
where:
- : the routing score (logit) for expert
- : the input token representation
- : the column vector from the weight matrix representing expert 's prototype
This framing as a dot product helps build intuition about how routing works. Recall that the dot product measures similarity between vectors: it is large when vectors point in similar directions and small (or negative) when they point in different directions. Therefore, experts with prototypes that align well with the input representation receive higher scores. Conversely, experts whose prototypes point away from the input in representation space receive lower scores.
During training, the router learns prototypes for token groups. One prototype might match scientific terms, while another matches conversational text. Training then sends each token group to a suitable expert.
The router parameters are typically initialized with standard techniques. As we covered in Part X, proper initialization prevents the router from starting with extreme biases toward particular experts. This keeps all experts have a chance to receive tokens during early training.
Routing Score Computation
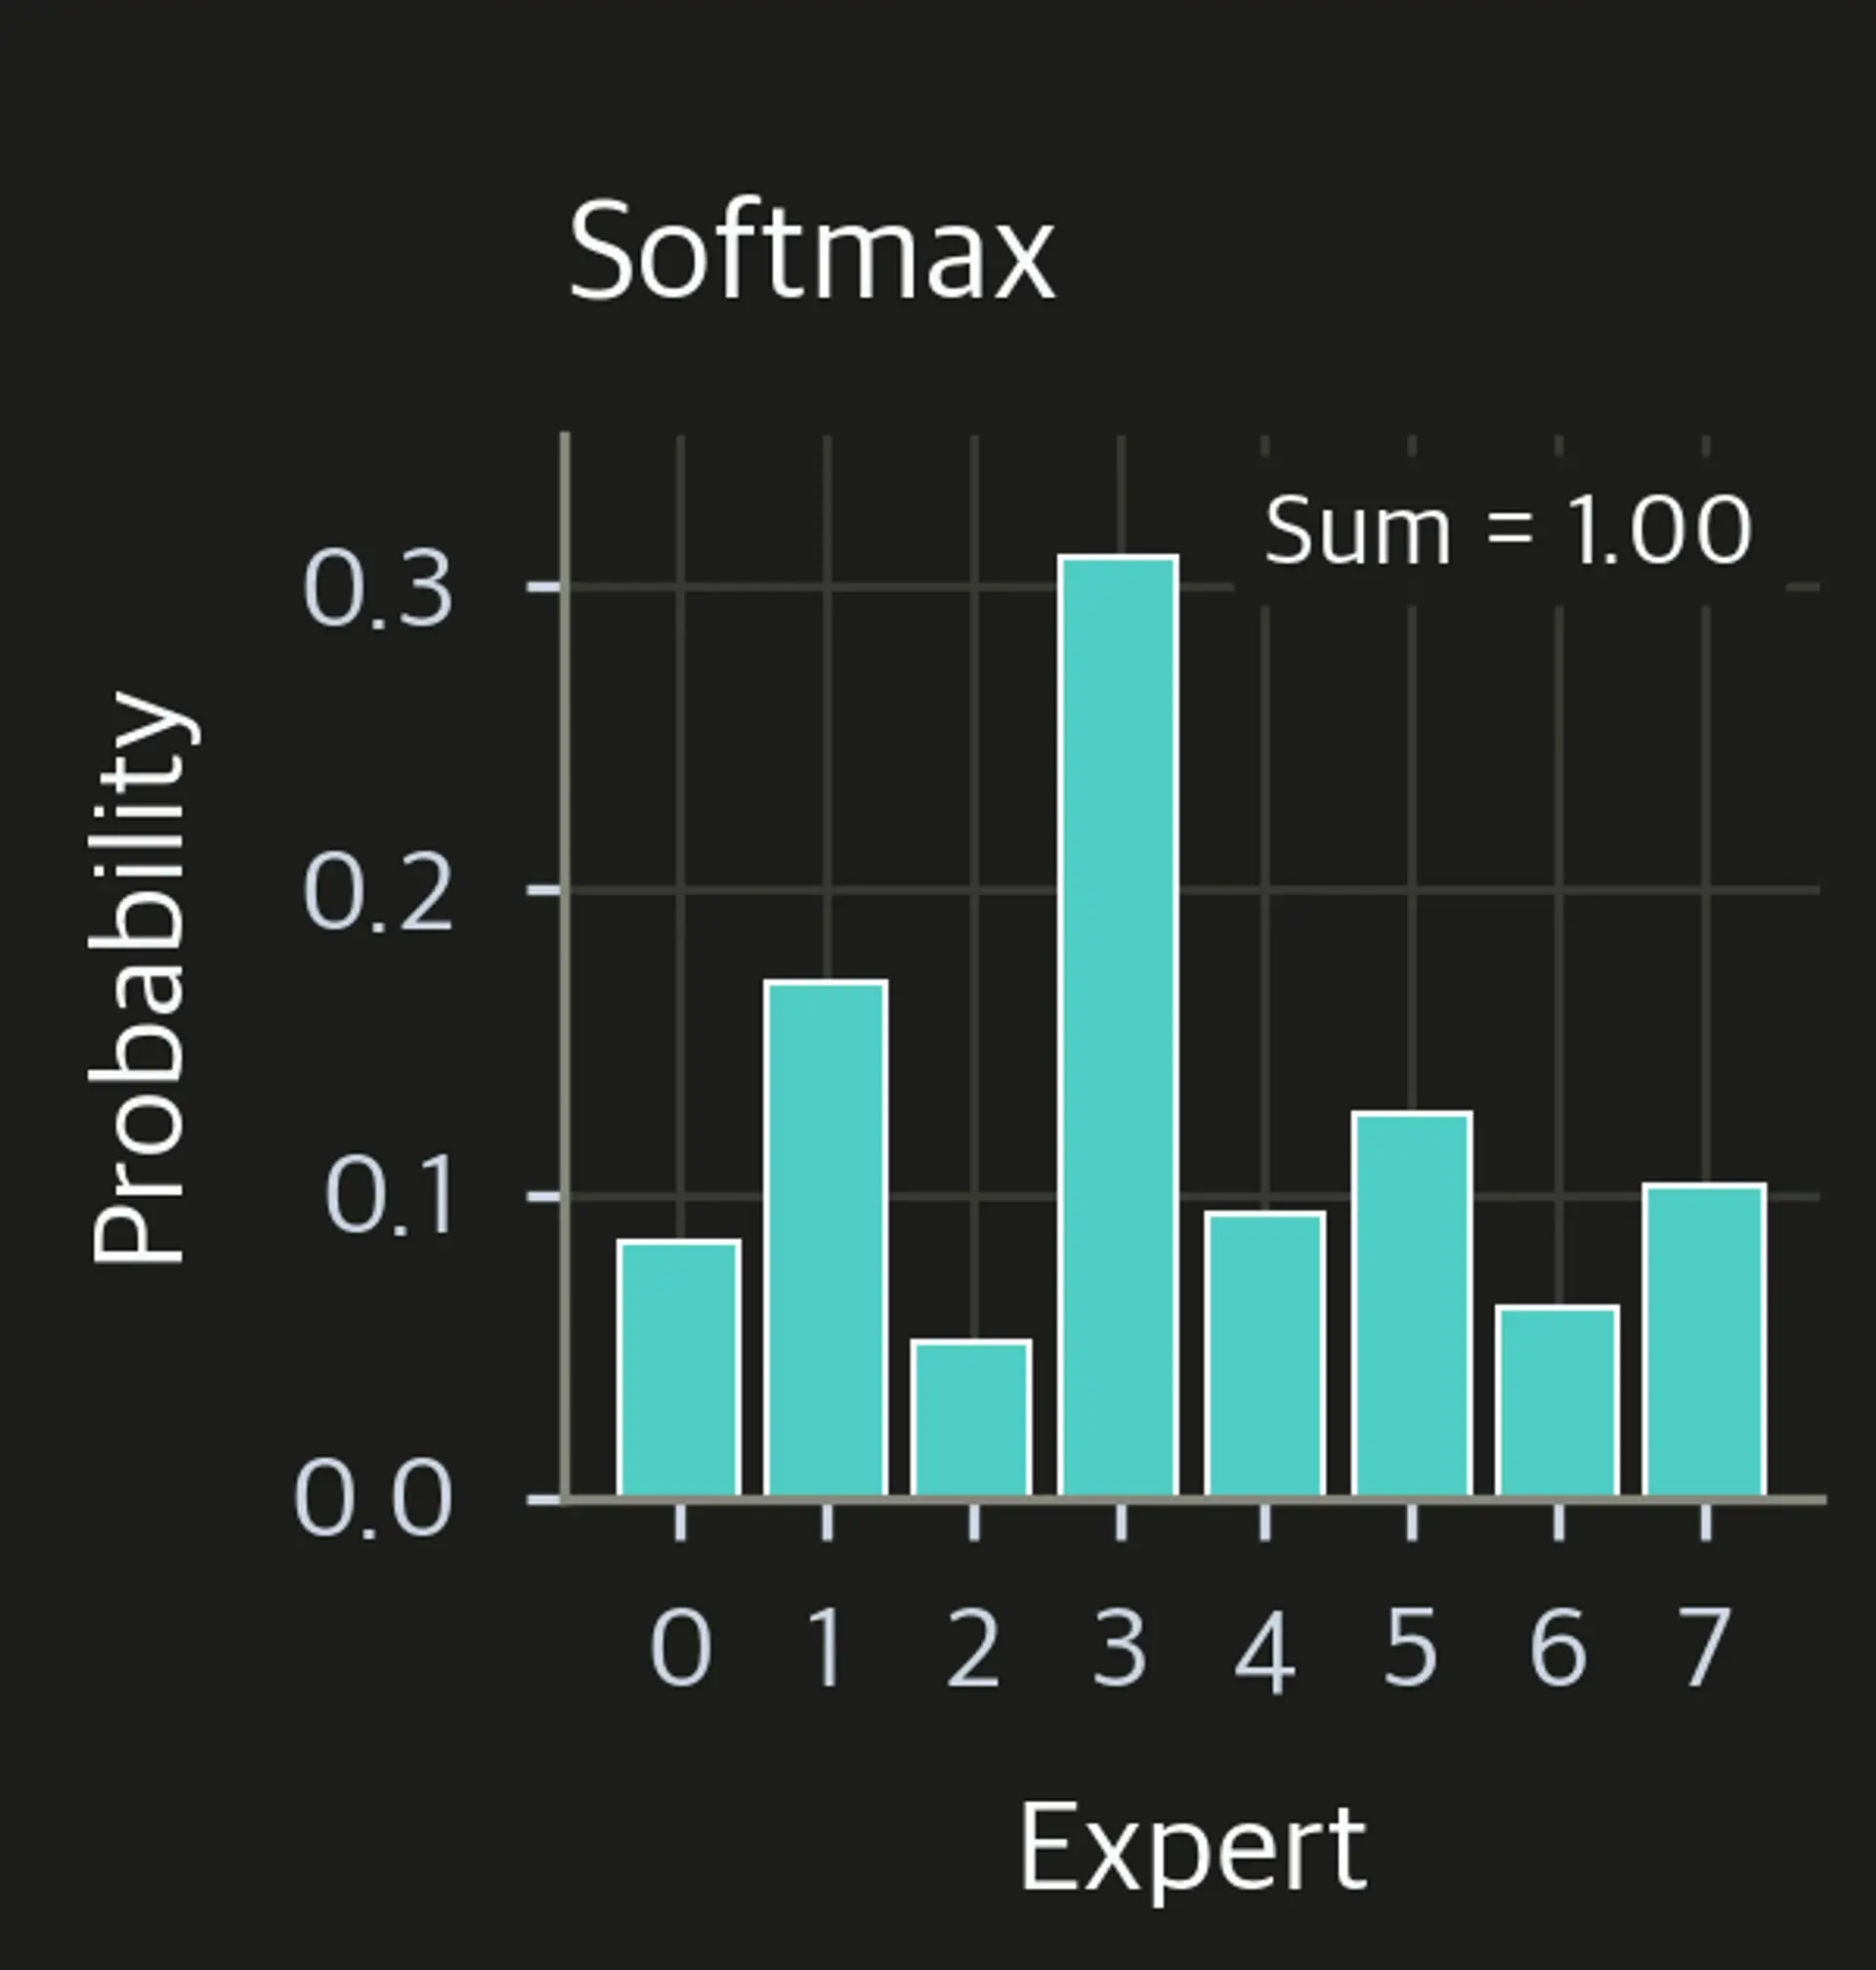
Raw routing logits from the linear projection must be converted into routing weights that determine how much each expert contributes to the output. The logits can be any real number, positive or negative, and they don't have any inherent probabilistic meaning. This transformation from arbitrary scores to real weights happens through a softmax function, creating a probability distribution over experts that we can interpret and use.
Softmax Gating
The softmax function is the standard tool for converting a vector of arbitrary real numbers into a probability distribution. In the context of routing, it turns our expert logits into normalized routing weights:
where:
- : the probability of selecting expert for input
- : the raw routing score (logit) for expert
- : the exponential function applied to the logit, so the value is positive
- : the sum of exponentials across all experts, serving as the normalizing constant
Let's see what this formula does. The exponential function serves two purposes: first, it ensures all values are positive (since probabilities cannot be negative); second, it amplifies differences between logits. If one expert has a logit of 3 and another has 1, the exponential makes the first about times larger, not just 2 points higher. This amplification makes the router's preferences more decisive.
The denominator is a normalizing constant. This keeps all probabilities sum to exactly 1. This normalization is needed because we want the routing weights to stand for a proper probability distribution.


These routing probabilities stand for the router's "confidence" that expert is appropriate for input . Higher probabilities indicate stronger preference, and we can compare probabilities across experts to understand the router's relative confidence in each option.
In a soft MoE (which we introduced conceptually in the sparse models chapter), the final output would be a weighted combination of all expert outputs:
where:
- : the combined output of the MoE layer
- : the routing probability for expert
- : the output computed by expert for input
However, this soft combination requires computing all expert outputs, which defeats the purpose of sparsity. If we must run every expert for every token, we gain no computational savings from having multiple specialized experts rather than one large one.
Hard Routing with Top-K Selection
Practical MoE systems use hard routing to obtain the computational benefits of sparsity: only the top- experts (by routing probability) are computed. The next chapter covers Top-K routing in detail, but the basic idea is needed to understand how the router functions in practice.
The process works in four steps:
- Compute all routing probabilities via softmax
- Select the highest-scoring experts
- Renormalize selected probabilities to sum to 1
- Compute only those experts
For example, with 8 experts and , only 2 experts run per token. This gives roughly 75% computational savings in the expert portion of the layer. The routing weights for selected experts become:
where:
- : the renormalized weight for selected expert
- : the original softmax probability for expert
- : the set of indices corresponding to the experts with highest scores
- : the sum of probabilities for the selected experts, used as a normalizing constant
This renormalization ensures the weighted combination of selected experts produces properly scaled outputs. Without renormalization, if the two selected experts had probabilities 0.3 and 0.2, they would sum to only 0.5, effectively scaling down the output. Renormalization adjusts them to approximately 0.6 and 0.4. This keeps the output magnitude remains appropriate.


Temperature Scaling
Some implementations add temperature scaling to the softmax to give additional control over routing behavior:
where:
- : the temperature-scaled probability for expert
- : the raw routing logit
- : the temperature parameter that controls the sharpness of the distribution
- : the exponentiated scaled logit; using amplifies differences, making the distribution sharper
This concept relates to the decoding temperature we covered in Part XXVIII, where temperature controls the randomness of text generation. The principle is the same: temperature modulates how peaked or flat the probability distribution is.
Lower temperatures sharpen the distribution, pushing probability mass toward the highest-scoring expert and approaching hard assignment to a single expert. Higher temperatures soften the distribution, spreading probability more evenly and approaching uniform routing where every expert has roughly equal chance of selection.


Temperature controls the "confidence" of routing decisions across different training phases. Early in training, higher temperatures encourage exploration across experts, preventing the model from committing too strongly to particular routing patterns before it has learned enough. Later, lower temperatures can encourage more decisive routing, letting the model use the specialization it has developed.
Router Training
Training the router presents a unique challenge that distinguishes it from standard neural network components: the router's output involves a discrete selection (which experts to use), but backpropagation requires continuous, differentiable operations. Discrete choices create discontinuities in the loss surface, making gradients undefined at decision boundaries. How, then, do gradients flow through routing decisions?
End-to-End Gradients
The key insight that lets router training is that although expert selection is discrete, the routing weights are continuous. The model cannot backpropagate through the binary decision of "use expert 3 instead of expert 5," but it can backpropagate through the continuous weights applied to the selected experts. Gradients flow through the weights applied to selected experts:
where:
- : the output of the MoE layer
- : the renormalized routing weight for selected expert
- : the output computed by expert
- : the set of indices for the selected experts
During backpropagation, the loss gradient with respect to router logits comes from two sources:
- Through the weights: How changing affects the weighted combination of expert outputs
- Through the softmax: How the raw logits affect the routing probabilities
For a selected expert , the gradient through routing weights follows the chain rule:
where:
- : the gradient of the loss with respect to the router logits
- : the gradient flowing back from the network output
- : the sensitivity of the output to the expert's weight
- : the gradient of the softmax (or Top-K) function
This gradient chain has an intuitive interpretation. The first term captures how much the overall loss depends on this MoE layer's output. The second term captures how much changing the weight of a particular expert would change that output (in effect the expert's output vector). The third term captures how sensitive the routing weight is to changes in the raw logit.
This gradient updates the router to assign higher weights to experts that produce better outputs for each input. If an expert produces an output that reduces the loss, the gradient will adjust the router to give that expert a higher weight for similar inputs in the future.
The Discrete Selection Problem
One subtlety deserves careful attention: gradients only flow through selected experts. If expert wasn't in the Top-K, there's no direct gradient signal about whether selecting it would have been better. The model never computes , so it cannot know how good that output would have been.
This creates a basic limitation in router learning. The router learns to improve its choices among selected experts based on their actual outputs, but has limited ability to discover that an unselected expert might be better. Imagine a scenario where expert 7 would be perfect for certain mathematical tokens, but the router never selects it for those tokens during early training. Without ever seeing expert 7's output on mathematical content, the gradient signal cannot tell the router to adjust toward selecting expert 7.
MoE systems can get stuck in suboptimal routing patterns. An expert might become permanently underutilized simply because random initialization didn't give it enough early opportunities.
Several techniques address this limitation:
- Load balancing losses penalize uneven expert usage, encouraging exploration of all experts by adding a penalty when some experts receive many more tokens than others
- Random routing occasionally selects experts not in the Top-K for gradient purposes, giving gradient signal about alternatives
- Auxiliary losses give additional training signals beyond the main task loss, guiding the router toward desirable behaviors
We'll explore these techniques in detail in the upcoming chapters on load balancing and auxiliary losses.
Gradient Scale Considerations
The routing weights are typically small values (especially when split across multiple experts), which can lead to gradient scaling issues. If two experts share a token with weights 0.5 and 0.5, the gradient flowing to each expert is scaled by 0.5. With more experts sharing, these weights become even smaller.
Beyond gradient scaling, another concern is numerical stability. If routing logits grow very large, the softmax can produce extreme probabilities (nearly 0 or 1), leading to vanishing gradients and unstable training. Some implementations use router z-loss to prevent routing logits from growing too large, maintaining stable training dynamics. The z-loss adds a penalty proportional to the log-sum-exp of routing logits:
where:
- : the router z-loss
- : the batch size
- : an input token representation in the batch
- : the raw routing score (logit) for expert
- : the partition function (denominator of softmax) for input
- : the Log-Sum-Exp of the logits, serving as a smooth approximation of the maximum logit
The log-sum-exp quantity is closely related to the maximum logit: as one logit grows much larger than the others, the log-sum-exp approaches that maximum value. By penalizing the squared log-sum-exp, the z-loss discourages any single expert from receiving extremely high routing scores. This encourages the router to produce moderate logits rather than extreme values, improving numerical stability throughout training.
Router Learned Behavior
What patterns emerge in trained routers? Understanding these patterns gives insight into how MoE models organize their computation and what specializations develop naturally during training. MoE routers learn real specialization, though patterns depend on the architecture, training data, and task.
Semantic Specialization
Studies of trained MoE language models show that experts often specialize by semantic domain. One expert might preferentially handle scientific text, another legal documents, another conversational content. This specialization emerges naturally from end-to-end training without any explicit labels about document types. The reason is that experts that specialize can model domain-specific patterns more precisely: an expert focused on legal language can learn the specific vocabulary, sentence structures, and logical patterns common in legal text.
To analyze this semantic specialization, we examine routing decisions on held-out data through a systematic process:
- Route many examples through the trained model
- Record which experts are selected for each token
- Aggregate by document type or topic
- Look for experts with concentrated domain preferences
These analyses reveal that domain specialization often develops in deeper layers, while earlier layers show more syntactic patterns. This makes sense from an information processing perspective: earlier layers establish basic linguistic structure, while later layers can afford to specialize on content-specific patterns.
Syntactic Patterns
Early MoE layers often route based on syntactic features rather than semantic content. Before the model can specialize on meaning, it must establish grammatical structure. Patterns observed in early layers include:
- Part-of-speech clustering: Experts that preferentially handle verbs, nouns, or punctuation
- Position effects: Some experts specialize in sentence-initial or sentence-final tokens
- Subword patterns: Different experts for complete words versus subword fragments
These syntactic patterns make sense given the information processing hierarchy: early layers need to handle positional and structural processing that applies broadly across domains. A verb requires similar processing whether it appears in a legal document or a casual conversation.
Token Frequency Effects
High-frequency tokens (function words, common subwords) often route to a small subset of experts, while rare tokens distribute more broadly across the expert pool. This asymmetry likely shows that common tokens have simpler, more predictable patterns that a few specialized experts can handle efficiently. Function words like "the," "is," and "of" behave consistently across contexts, so dedicating experts to them makes sense.
Rare tokens, on the other hand, appear in diverse contexts and may benefit from accessing different experts depending on their specific usage. A rare technical term might need different processing when appearing in a definition versus an application.
Layer-by-Layer Evolution
Routing patterns differ across layers in the model, showing a progression from general to specific processing. A common pattern observed in trained models:
- Early layers: More uniform routing, syntactic specialization
- Middle layers: Emerging domain specialization, more concentrated routing
- Later layers: Strong specialization, decisive routing (lower entropy in routing distribution)
This progression mirrors the general finding that transformer representations become more abstract and task-specific in deeper layers. Early layers establish shared representations useful for all types of content, while later layers can afford to specialize because they build on this shared foundation.

Worked Example
Let's trace through routing computation for a concrete example to solidify the concepts. Working through the math shows how formulas produce routing decisions. Suppose we have:
- 4 experts
- Input dimension
- An input token representation:
And a router weight matrix:
Step 1: Compute routing logits
The first step applies the linear projection to compute raw scores for each expert. We multiply the input vector by the weight matrix:
For expert 1 (first column), we compute the dot product between the input and the first column of the weight matrix:
Computing all four expert scores using the same dot product approach:
Expert 3 has the highest logit (0.52), followed by Expert 2 (0.30). Expert 1 and Expert 4 have negative scores, showing the input doesn't align well with their prototypes.
Step 2: Apply softmax
Next, we convert these raw logits to probabilities. First, compute the exponentials to ensure positive values:
Sum:
Divide each exponential by the sum to get normalized probabilities:
Notice how the exponential amplified the differences: Expert 3's logit is only 0.22 higher than Expert 2's, but its probability is about 25% higher ((0.36) vs (0.29)).
Step 3: Top-2 selection
The two highest-scoring experts are Expert 3 (0.36) and Expert 2 (0.29). These are the only experts that compute their outputs.
Renormalized weights ensure the selected experts' contributions sum to 1:
The final output is:
Only experts 2 and 3 are computed, saving roughly 50% of expert computation compared to running all four experts. Expert 3 contributes slightly more to the output due to its higher routing score.


Code Implementation
Let's implement a gating network from scratch to see these concepts in action.
import numpy as np
import torch

# Set random seed for reproducibility
torch.manual_seed(42)
np.random.seed(42)
Basic Router Module
We start with the core router implementation. The router is a linear layer that projects token representations to expert scores.
import torch
import torch.nn as nn
import torch.nn.functional as F


class Router(nn.Module):
    """
    Gating network for Mixture of Experts.
    Routes tokens to top-k experts based on learned routing scores.
    """

    def __init__(self, d_model: int, num_experts: int, top_k: int = 2):
        super().__init__()
        self.num_experts = num_experts
        self.top_k = top_k

        # Single linear layer: projects from d_model to num_experts
        # No bias term, common in production MoE implementations
        self.gate = nn.Linear(d_model, num_experts, bias=False)

    def forward(self, x: torch.Tensor):
        """
        Compute routing weights for input tokens.

        Args:
            x: Input tensor of shape (batch_size, seq_len, d_model)

        Returns:
            routing_weights: Weights for selected experts (batch, seq, top_k)
            selected_experts: Indices of selected experts (batch, seq, top_k)
            router_probs: Full probability distribution (batch, seq, num_experts)
        """
        # Compute routing logits
        logits = self.gate(x)  # (batch, seq, num_experts)

        # Convert to probabilities via softmax
        router_probs = F.softmax(logits, dim=-1)

        # Select top-k experts
        routing_weights, selected_experts = torch.topk(
            router_probs, self.top_k, dim=-1
        )

        # Renormalize weights to sum to 1
        routing_weights = routing_weights / routing_weights.sum(
            dim=-1, keepdim=True
        )

        return routing_weights, selected_experts, router_probs
Let's verify the router produces expected outputs:
# Create a router with 8 experts, selecting top-2
d_model = 256
num_experts = 8
router = Router(d_model, num_experts, top_k=2)

# Simulate a batch of token representations
batch_size = 2
seq_len = 4
x = torch.randn(batch_size, seq_len, d_model)

# Get routing decisions
routing_weights, selected_experts, router_probs = router(x)Input shape: torch.Size([2, 4, 256]) Routing weights shape: torch.Size([2, 4, 2]) Selected experts shape: torch.Size([2, 4, 2]) First token routing probabilities (all experts): [0.184 0.073 0.083 0.066 0.336 0.049 0.031 0.178] First token selected experts: [4, 0] First token weights for selected experts: [0.646 0.354] Weights sum: 1.000
The router produces probability distributions over all experts, then selects the top-2 and renormalizes their weights.
Routing Score Analysis
To understand router behavior, let's examine how routing probabilities distribute across experts for different inputs.
def analyze_routing_distribution(router, num_samples=1000, d_model=256):
    """
    Analyze how the router distributes tokens across experts.
    """
    # Generate random token representations
    x = torch.randn(num_samples, 1, d_model)

    with torch.no_grad():
        _, selected_experts, router_probs = router(x)

    # Count how often each expert is selected
    expert_counts = torch.zeros(router.num_experts)
    for i in range(router.num_experts):
        expert_counts[i] = (selected_experts == i).sum().item()

    # Compute mean probability assigned to each expert
    mean_probs = router_probs.squeeze(1).mean(dim=0)

return expert_counts, mean_probs# Analyze an untrained router
counts, mean_probs = analyze_routing_distribution(router)Expert selection counts (out of 2000 selections): Expert 0: 265 ██████████████████████████████████████ Expert 1: 251 ████████████████████████████████████ Expert 2: 261 █████████████████████████████████████ Expert 3: 215 ██████████████████████████████ Expert 4: 241 ██████████████████████████████████ Expert 5: 227 ████████████████████████████████ Expert 6: 278 ████████████████████████████████████████ Expert 7: 262 █████████████████████████████████████ Mean routing probabilities: Expert 0: 0.126 ██████████ Expert 1: 0.126 ██████████ Expert 2: 0.128 ██████████ Expert 3: 0.120 █████████ Expert 4: 0.122 █████████ Expert 5: 0.122 █████████ Expert 6: 0.129 ██████████ Expert 7: 0.126 ██████████
With random initialization, the router distributes fairly evenly across experts. This is expected before training shapes the routing behavior.


Visualizing Routing Entropy
Routing entropy measures how "decisive" the router is. Low entropy means the router strongly prefers specific experts; high entropy means uncertainty across many experts.
def compute_routing_entropy(router_probs):
    """
    Compute entropy of routing distributions.
    Higher entropy = more uniform, lower = more concentrated.
    """
    # Avoid log(0)
    probs = router_probs.clamp(min=1e-10)
    entropy = -torch.sum(probs * torch.log(probs), dim=-1)
    return entropy


# Compute entropy for our sample
_, _, router_probs = router(x)
entropies = compute_routing_entropy(router_probs)# Maximum possible entropy (uniform distribution over 8 experts)
max_entropy = np.log(num_experts)Maximum entropy (uniform over 8 experts): 2.079 Mean observed entropy: 1.904 Entropy ratio (observed/max): 91.56%
An untrained router produces near-maximum entropy, showing uniform routing. Training should reduce this as the router learns to make more decisive choices.
Simulating Trained Router Behavior
Let's simulate what happens when a router learns domain-specific patterns. We'll create synthetic "domain" embeddings and train the router to recognize them.
This is a supervised toy classification setup: we generate synthetic "domains" as Gaussian clusters and directly train the router to predict the domain label. If the clusters are well separated (large prototype_scale) and noise is small (noise_std), a linear gate can drive logits to large magnitudes, making softmax saturate and the loss appear to drop to ~0 in just a few optimization steps.
To keep the curve informative (and connect to the stability discussion above), the demo below uses overlapping domains and adds a small router z-loss term (z_loss_coef) to discourage runaway logits.
# Create synthetic domain representations
# Imagine these are averaged representations from different document types
num_domains = 4
prototype_scale = 1.0
noise_std = 0.8
batch_size_per_domain = 64

# NOTE: If you crank up prototype_scale and reduce noise_std, this becomes
# an almost trivial supervised classification problem and the loss can drop
# to ~0 in just a few optimization steps (softmax saturation).
domain_prototypes = torch.randn(num_domains, d_model) * prototype_scale

# Create a router with one expert per domain
domain_router = Router(d_model, num_domains, top_k=1)

# Simulate "labeled" training: each sample comes from a known domain
# We'll train the router to route domain samples to corresponding experts

z_loss_coef = 1e-2
optimizer = torch.optim.Adam(
    domain_router.parameters(), lr=0.005, weight_decay=1e-4
)

losses = []
for epoch in range(200):
    epoch_loss = 0
    for domain_idx in range(num_domains):
        # Generate samples from this domain (prototype + noise)
        samples = (
            domain_prototypes[domain_idx]
            + torch.randn(batch_size_per_domain, d_model) * noise_std
        )
        samples = samples.unsqueeze(1)  # Add seq dimension

        # Train on logits directly for numerical stability
        logits = domain_router.gate(samples).squeeze(1)  # (batch, num_domains)
        labels = torch.full(
            (logits.shape[0],),
            domain_idx,
            dtype=torch.long,
            device=logits.device,
        )

        # Cross-entropy: encourage routing to the correct expert
        nll = F.cross_entropy(logits, labels)

        # Router z-loss: discourages runaway logits (keeps softmax from saturating)
        z = torch.logsumexp(logits, dim=-1)
        z_loss = (z**2).mean()

        loss = nll + z_loss_coef * z_loss

        optimizer.zero_grad()
        loss.backward()
        optimizer.step()

        epoch_loss += loss.item()

    losses.append(epoch_loss / num_domains)
The router quickly learns to distinguish domain-specific patterns. Let's verify it routes correctly:
# Test routing accuracy on new samples
correct = 0
total = 0
domain_accuracies = []

with torch.no_grad():
    for domain_idx in range(num_domains):
        samples = (
            domain_prototypes[domain_idx] + torch.randn(100, d_model) * 0.3
        )
        samples = samples.unsqueeze(1)

        _, selected, _ = domain_router(samples)
        selected = selected.squeeze()

        # Calculate accuracy for this domain
        domain_acc = (selected == domain_idx).float().mean().item()
        domain_accuracies.append(domain_acc)

        correct += (selected == domain_idx).sum().item()
total += 100Routing accuracy: 100.0% Per-domain accuracy: Domain 0: 100.0% Domain 1: 100.0% Domain 2: 100.0% Domain 3: 100.0%
The trained router successfully learns to route tokens from different domains to appropriate experts.

Router Weight Visualization
We can visualize the router's learned prototypes to understand what patterns it captures.
# Extract router weights for visualization
weights = domain_router.gate.weight.detach().numpy()
Each row shows a distinct pattern, representing the "prototype" that input must match to route to that expert. The router learns to position these prototypes to distinguish between domain-specific representations.
Key Parameters
The key parameters for the Gating Network are:
- d_model: The dimension of input token representations.
- num_experts: The total number of experts available in the layer.
- top_k: The number of experts selected for each token. Common values are 1 or 2.
- bias: Whether to include a bias term in the linear projection. Typically set to
False.
Limitations and Impact
The gating network design we've covered is the standard approach used in models like Switch Transformer and Mixtral. While effective, this design has important limitations that shape MoE research and practice.
Routers make discrete decisions while training requires continuous gradients. The standard approach handles this by flowing gradients through routing weights, not expert selection. This works but creates blind spots: the model never learns whether unselected experts might have been better choices. Several techniques address this limitation. Load balancing losses encourage the router to explore all experts by penalizing uneven usage. Random routing occasionally computes non-selected experts for gradient purposes. And capacity factors limit how many tokens any single expert can handle, forcing distribution across experts. We'll explore these techniques in the upcoming chapters on load balancing and auxiliary losses.
Another limitation is the simplicity of the routing decision. A single linear layer might not capture complex routing logic. Some research explores hierarchical routers (first choose an expert cluster, then an expert within it) or multi-layer routers. However, the simple linear approach remains dominant because more complex routers add overhead and don't consistently improve performance.
Despite these limitations, gating networks let sparse expert models match or exceed dense-model quality at lower computational cost. The router learns specialization by routing different content types to appropriate experts, showing that simple gating mechanisms can capture structure in language. This specialization emerges from end-to-end training without explicit supervision about which expert should handle which content. The router discovers divisions of labor by learning which expert produces better outputs for each input type.
Summary
Gating networks serve as the decision-making component in Mixture of Experts architectures, determining which experts process each token. This chapter covers:
-
Router architecture: Standard routers use a single linear layer projecting token representations to expert scores. This simple design balances computational efficiency with sufficient expressivity.
-
Routing score computation: Raw logits pass through softmax to produce a probability distribution over experts. Top-K selection then identifies the experts used for computation, with renormalized weights for combining their outputs.
-
Router training: Gradients flow through routing weights (which are continuous) even though expert selection is discrete. This creates blind spots for unselected experts, motivating auxiliary training techniques.
-
Learned behavior: Trained routers exhibit real specialization, including semantic domain preferences, syntactic patterns, and layer-dependent routing strategies. This specialization emerges naturally from end-to-end training.
The next chapter covers Top-K routing in detail, examining how the number of selected experts affects model capacity, computation costs, and training dynamics.
Quiz
Ready to test your understanding? Take this quick quiz to reinforce what you've learned about gating networks in Mixture of Experts architectures.
Gating Networks Quiz
Reference
Citation details
Cite or share this article.
Continue with the full handbook
This chapter is part of Language AI Handbook. Use the handbook page to browse the complete table of contents and continue reading in sequence.
Explore Language AI HandbookStay up to date
Get articles, book updates, and news delivered to your inbox.
No spam, unsubscribe anytime.
Join the community
Sign in to remove popups, track your reading progress, and join the discussion.

Comments
No comments yet. Be the first to share your thoughts!