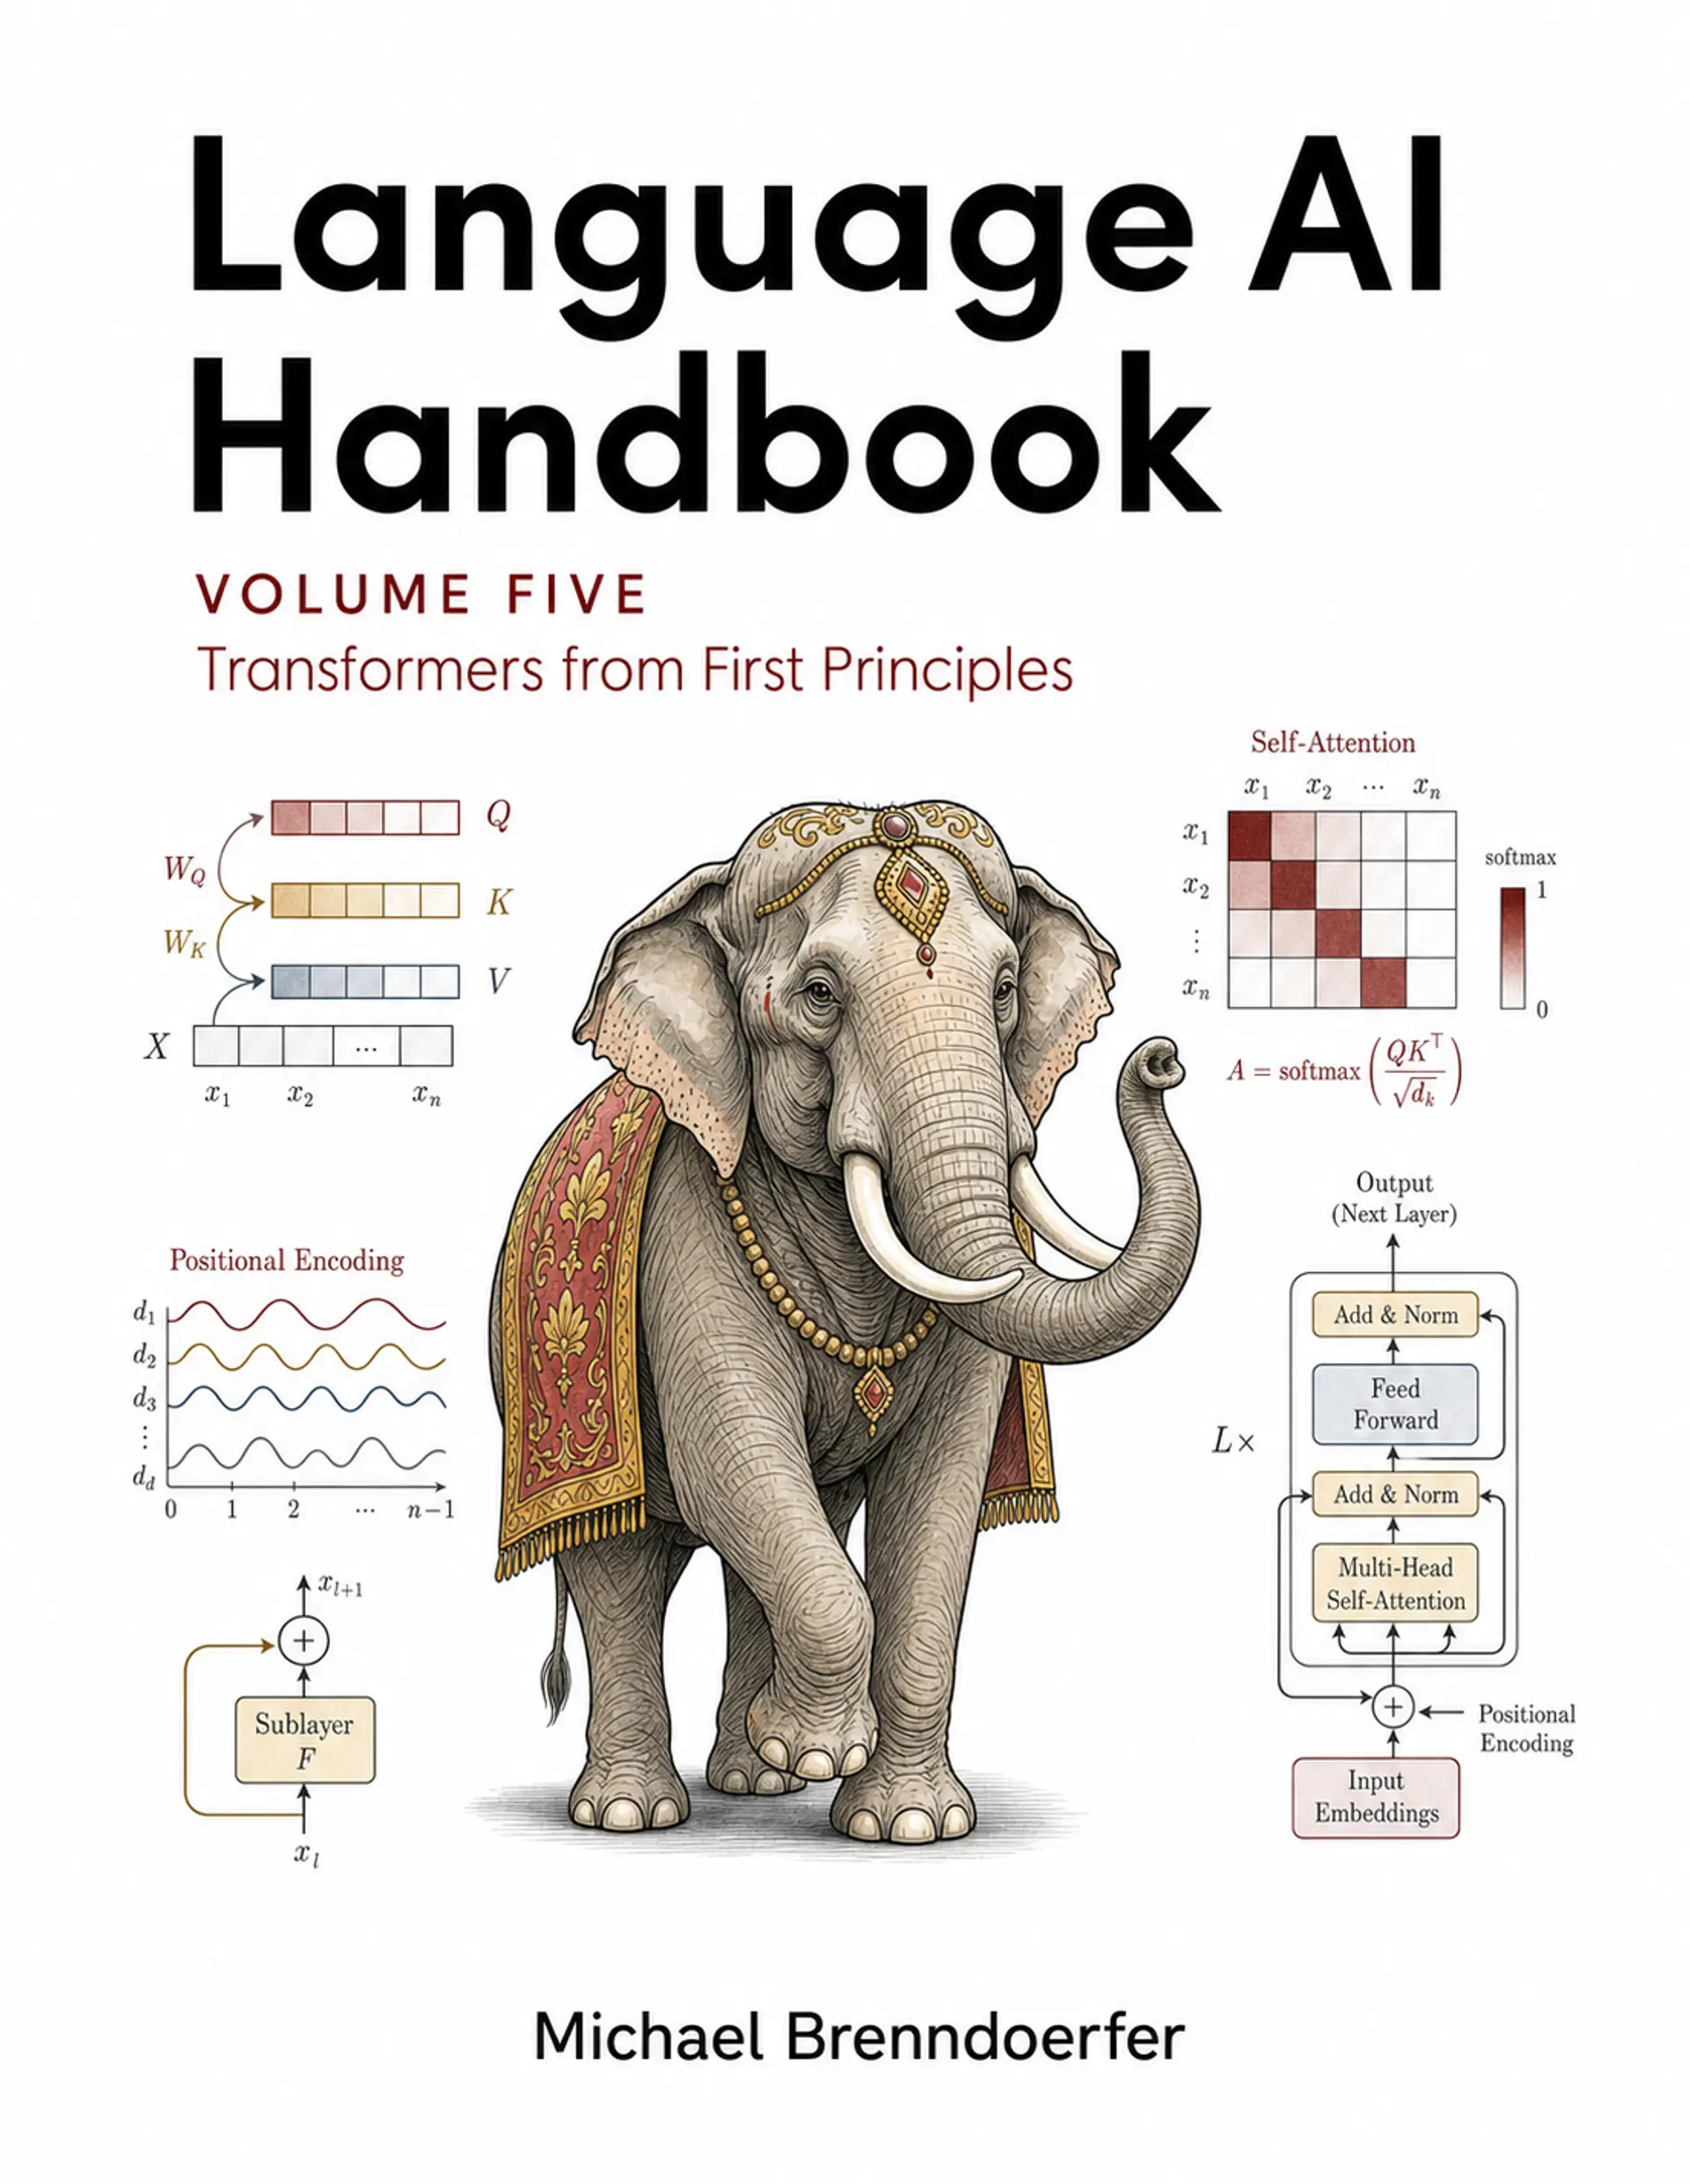
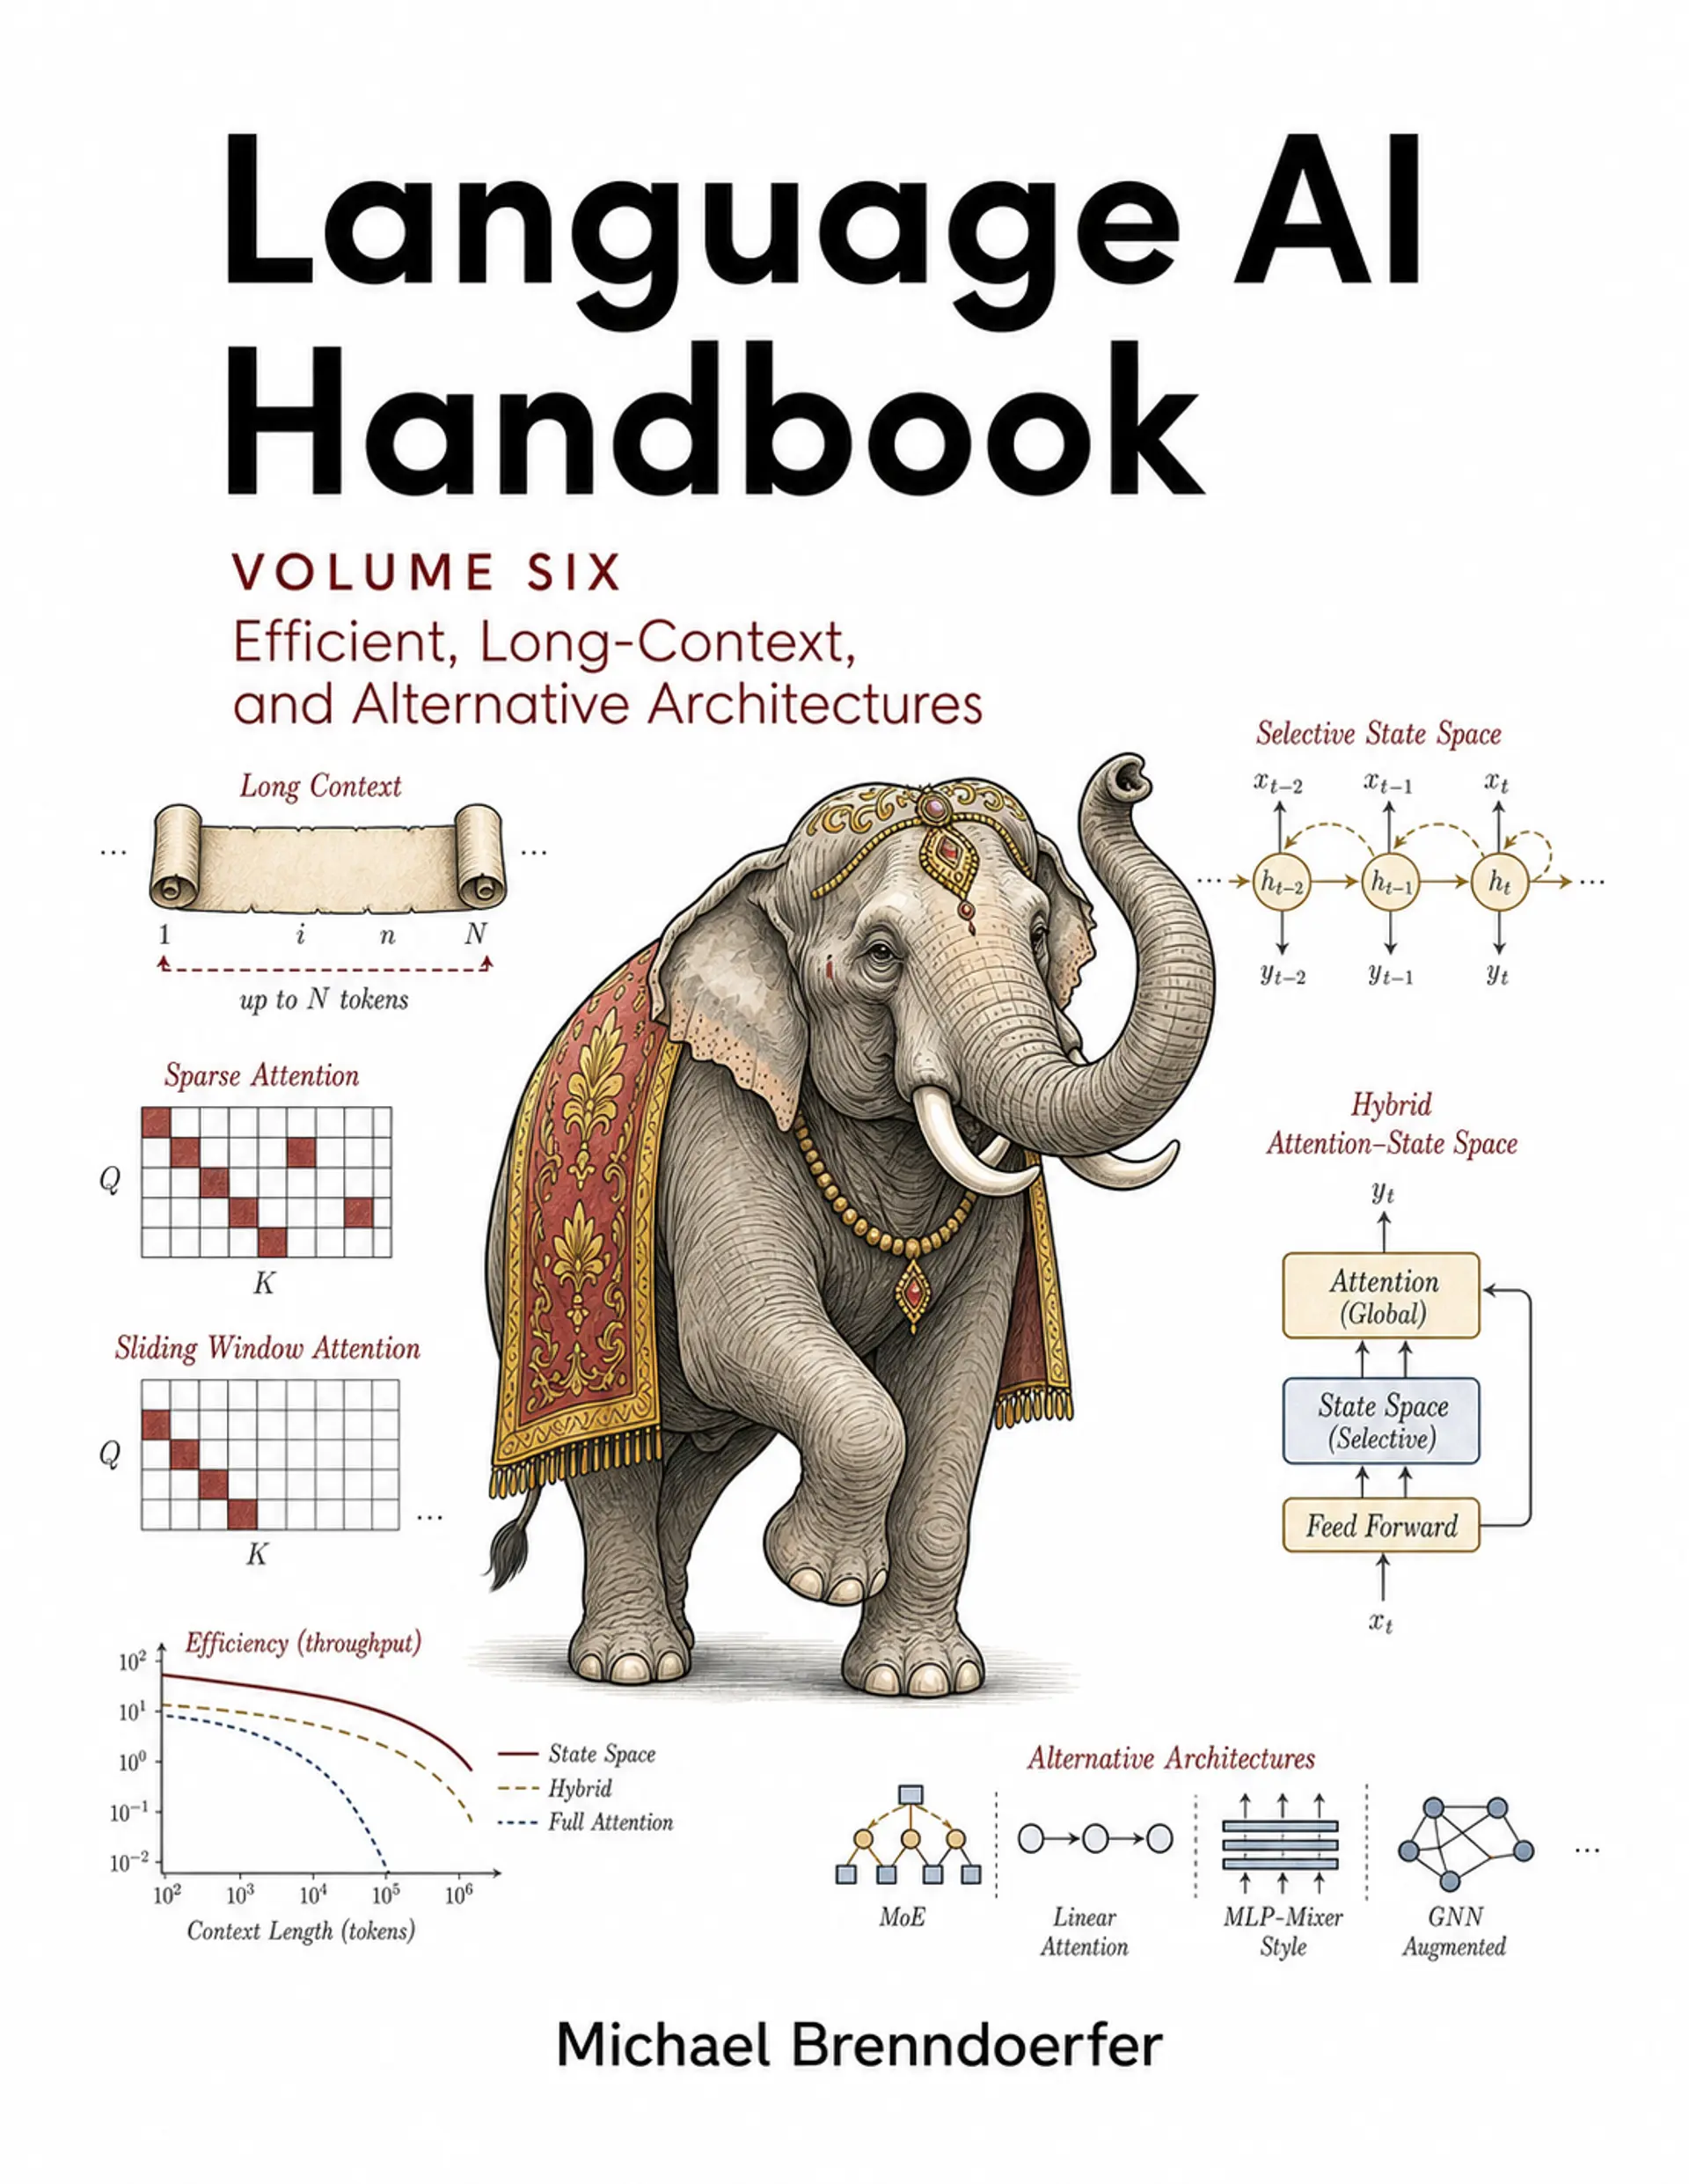
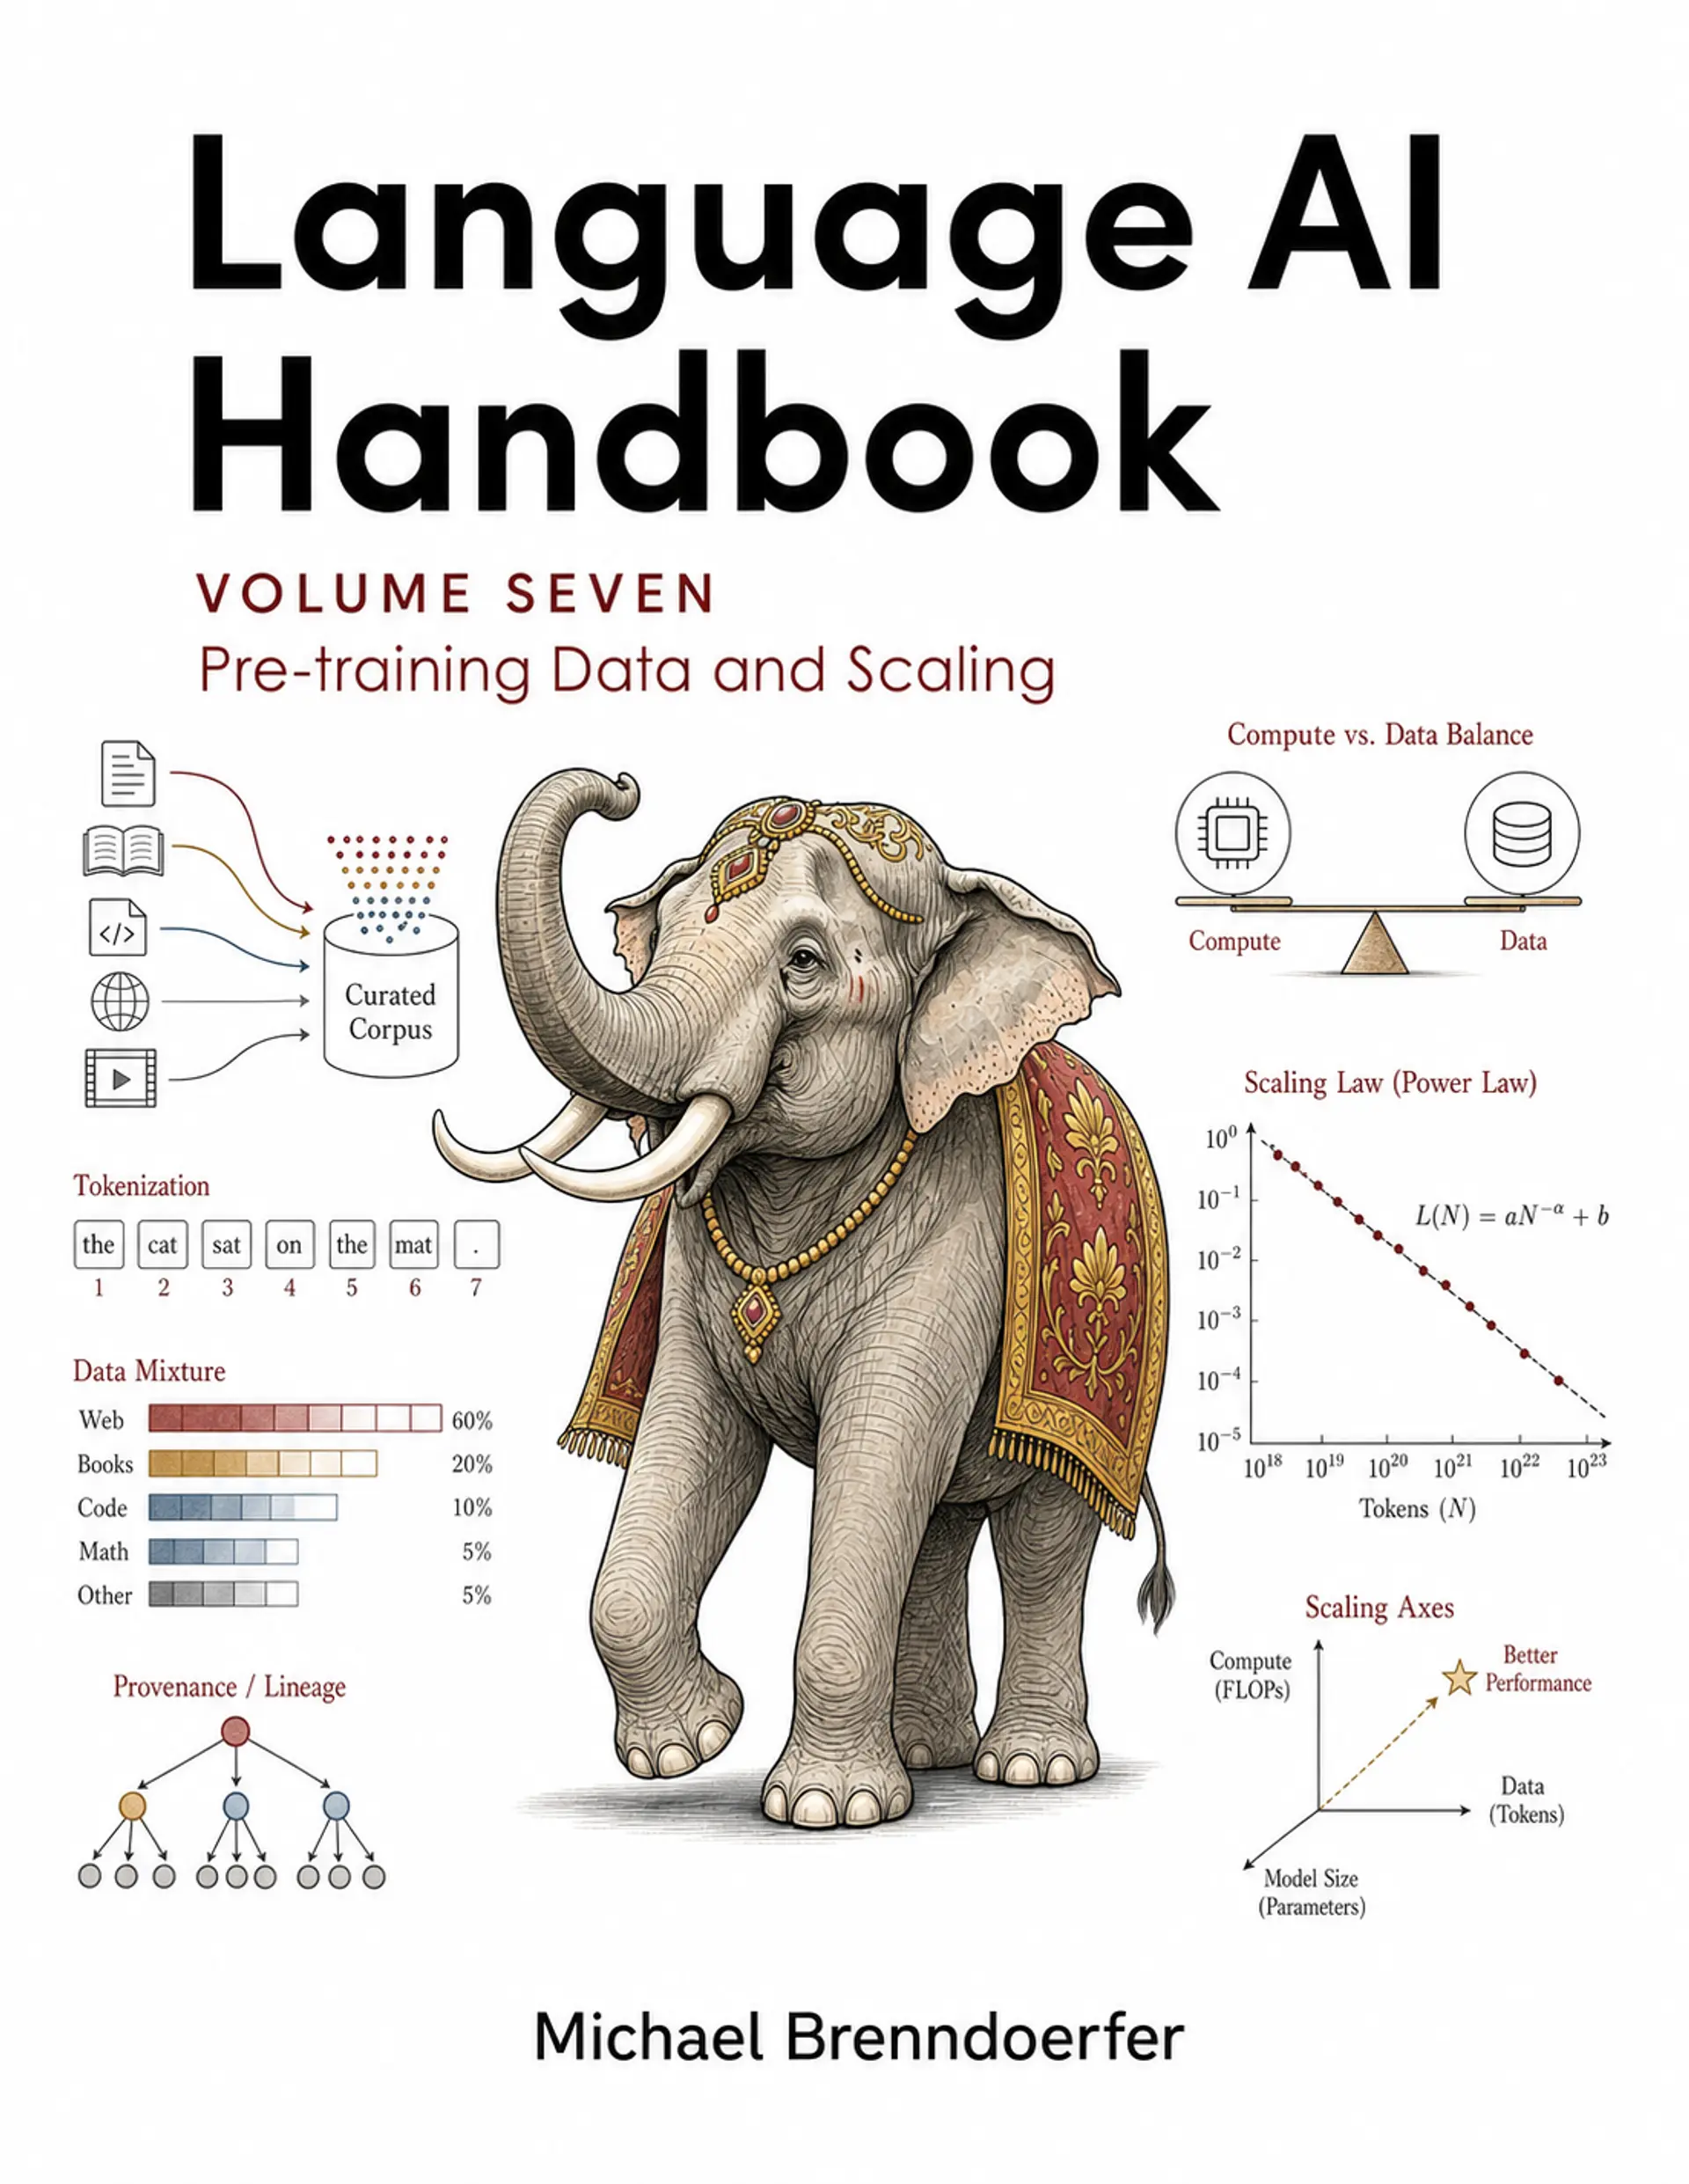
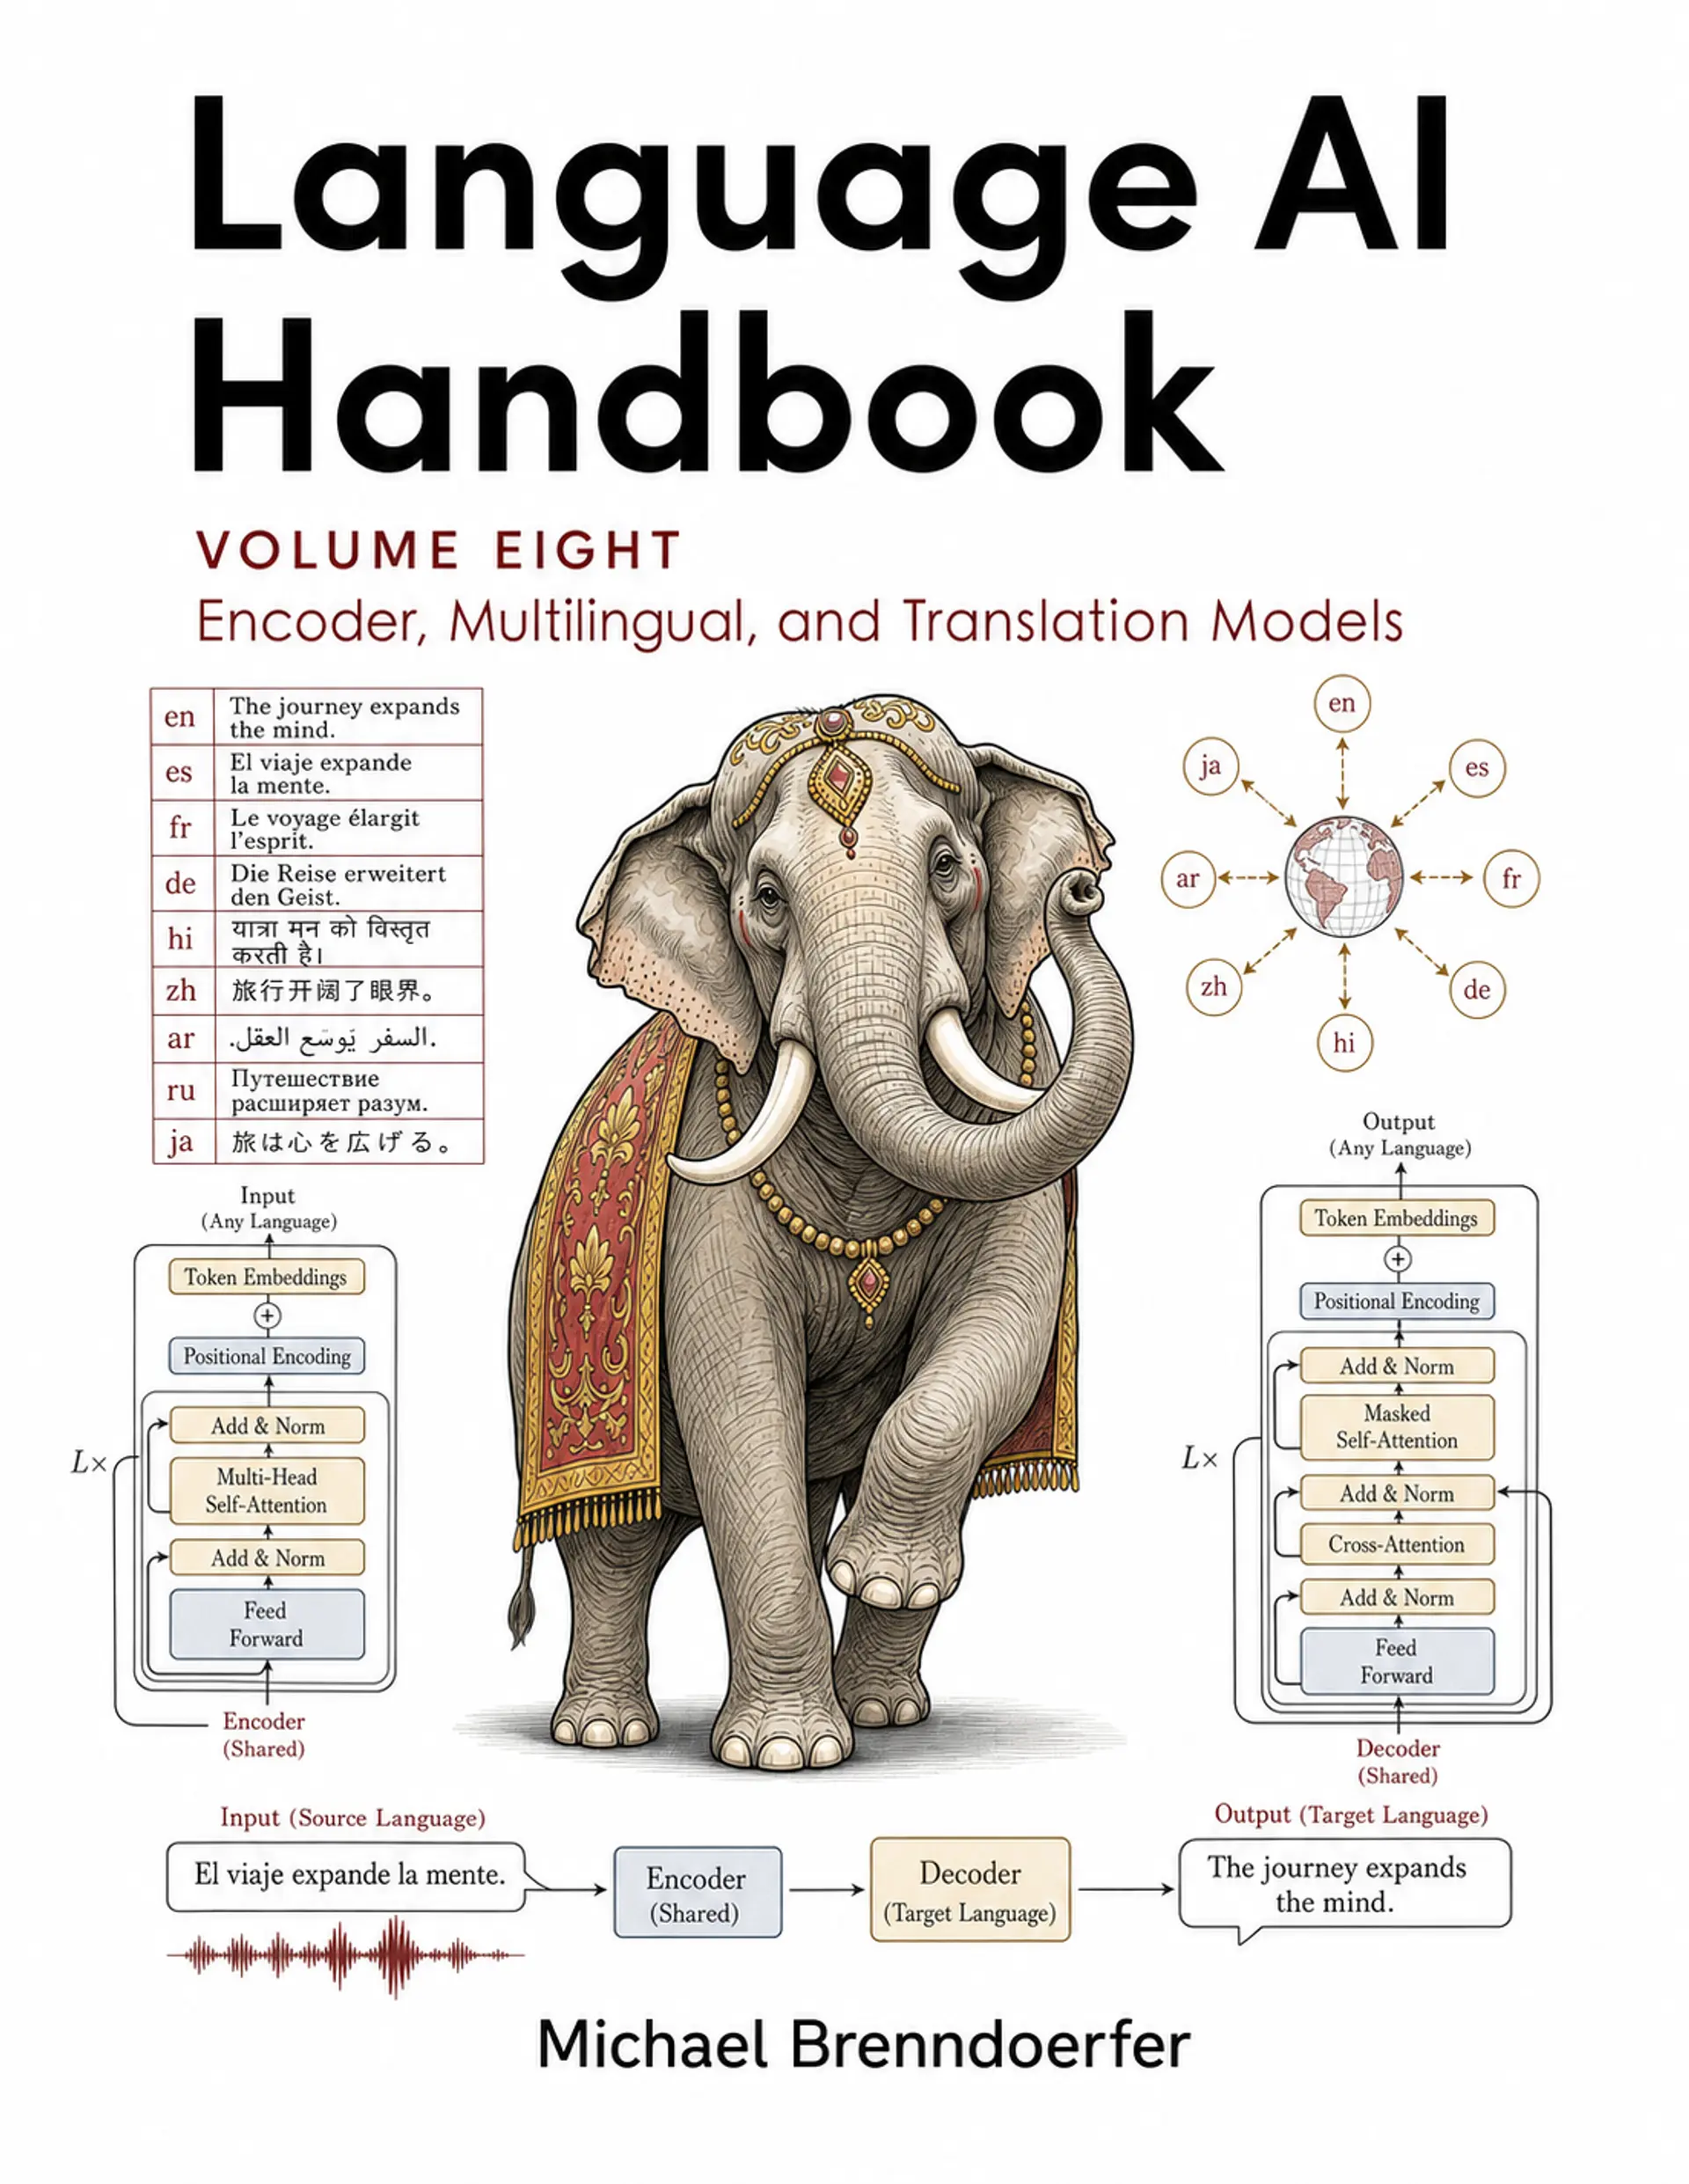
Language AI Handbook Cover

BY MICHAEL BRENNDOERFER

Language AI Handbook

Start with classical NLP, then work through transformers, LLM training, evaluation, and production

The book spans 20 volumes. Read in order, or browse the contents to find the topic you need.

12,550 pages across 418 chapters
Browse contents

Read Language AI Handbook free online

The Language AI Handbook connects the pieces of modern language AI. We begin with classical NLP, build up to transformers and LLM training, then cover retrieval, evaluation, safety, and production deployment.

Explore the book’s 20 volumes

Language AI Handbook is organised into 20 volumes, plus an appendix. Each volume covers a subject, divided into parts and chapters. Read from the beginning, or choose the volume you need.

418 published chapters · Free to read online

Start at chapter one

Part I

Text as Data

5 chapters

Part II

Classical Text Representations

9 chapters
06Bag of WordsCovers document-term matrix construction, vocabulary building from corpus, word counting and frequency vectors, sparse matrix representation (CSR/CSC formats), vocabulary pruning (min_df, max_df), binary vs count representations, limitations of word order loss.51 min07N-gramsCovers bigram and trigram extraction, n-gram vocabulary explosion, n-gram frequency distributions, Zipf's law in n-grams, character n-grams for robustness, skip-grams and flexible windows, n-gram indexing for search.47 min08N-gram Language ModelsCovers Markov assumption and chain rule, maximum likelihood estimation, probability calculation for sequences, handling unseen n-grams, start and end tokens, generating text from n-gram models, model storage and lookup efficiency.58 min09Smoothing TechniquesCovers add-one (Laplace) smoothing, add-k smoothing and tuning, Good-Turing smoothing derivation, Kneser-Ney smoothing intuition and formula, interpolation vs backoff, modified Kneser-Ney, comparing smoothing methods empirically.56 min10PerplexityCovers cross-entropy definition and derivation, perplexity as branching factor, relationship to bits-per-character, held-out evaluation methodology, perplexity vs downstream performance, comparing models with perplexity, perplexity limitations and caveats.63 min11Term FrequencyCovers raw term frequency, log-scaled term frequency, boolean term frequency, augmented term frequency, L2-normalized frequency vectors, term frequency sparsity patterns, efficient term frequency computation.46 min12Inverse Document FrequencyCovers document frequency calculation, IDF formula derivation, IDF intuition (rare words matter more), smoothed IDF variants, IDF across corpus splits, relationship to information theory, implementing IDF efficiently.59 min13TF-IDFCovers TF-IDF formula and variants, TF-IDF vector computation, TF-IDF normalization options, BM25 as TF-IDF extension, document similarity with TF-IDF, TF-IDF for feature extraction, sklearn TfidfVectorizer deep dive.51 min14BM25Covers BM25 derivation from probabilistic IR, saturation parameter k1, length normalization parameter b, BM25+ and BM25L variants, field-weighted BM25, implementing BM25 scoring, BM25 vs TF-IDF empirically.52 min

Part III

Distributional Semantics

4 chapters
Volume 1 · 18 chapters

Part IV

Word Embeddings

9 chapters
19Skip-gram ModelCovers skip-gram architecture diagram, input/output representations, softmax over vocabulary, skip-gram objective function, training data generation, window size hyperparameter, skip-gram vs CBOW intuition.41 min20CBOW ModelCovers CBOW architecture, context word averaging, CBOW objective function, CBOW vs skip-gram training speed, CBOW for frequent words, implementing CBOW forward pass, CBOW gradient derivation.52 min21Negative SamplingCovers softmax computational bottleneck, negative sampling objective derivation, sampling distribution (unigram^0.75), number of negatives hyperparameter, negative sampling gradient computation, NCE vs negative sampling, implementing efficient sampling.47 min22Hierarchical SoftmaxCovers binary tree construction (Huffman coding), path probability computation, hierarchical softmax objective, gradient computation along paths, tree structure impact on learning, hierarchical softmax vs negative sampling, when to use each approach.53 min23Word2Vec TrainingCovers data preprocessing pipeline, subsampling frequent words, learning rate scheduling, minibatch vs online training, convergence monitoring, gensim Word2Vec usage, training from scratch in PyTorch.50 min24Word AnalogyCovers vector arithmetic for analogies, parallelogram model, analogy evaluation datasets, 3CosAdd vs 3CosMul methods, analogy accuracy metrics, limitations of analogy evaluation, what analogies reveal about embeddings.49 min25GloVeCovers GloVe objective function derivation, weighted least squares formulation, relationship to matrix factorization, weighting function design, bias terms in GloVe, GloVe vs Word2Vec comparison, training GloVe efficiently.47 min26FastTextCovers character n-gram representation, word vector as n-gram sum, FastText architecture, handling OOV words, morphological awareness, FastText for morphologically rich languages, training FastText models.51 min27Embedding EvaluationCovers intrinsic vs extrinsic evaluation, word similarity datasets (SimLex, WordSim), analogy accuracy, embedding visualization (t-SNE, UMAP), downstream task evaluation, embedding bias detection, evaluation pitfalls.54 min

Part V

Subword Tokenization

8 chapters
28The Vocabulary ProblemCovers OOV word problem, vocabulary size explosion, rare word representation, morphological productivity, compound words, code and technical text, the case for subword units.48 min29Byte Pair EncodingCovers BPE algorithm step-by-step, merge rules learning, vocabulary size control, BPE encoding procedure, BPE decoding procedure, BPE implementation from scratch, BPE hyperparameters.46 min30WordPieceCovers WordPiece vs BPE differences, likelihood objective for merges, greedy tokenization algorithm, ## prefix notation, WordPiece in BERT, training WordPiece tokenizers, handling unknown characters.48 min31Unigram Language Model TokenizationCovers unigram LM formulation, EM algorithm for training, Viterbi decoding for tokenization, sampling multiple segmentations, subword regularization, unigram vs BPE comparison, SentencePiece unigram mode.55 min32SentencePieceCovers treating text as raw bytes, whitespace handling (▁ prefix), BPE and unigram modes, training from raw text, pretokenization elimination, SentencePiece in production, multilingual tokenization.44 min33Tokenizer TrainingCovers corpus preparation, vocabulary size selection, special tokens configuration, training with HuggingFace tokenizers, saving and loading tokenizers, tokenizer versioning, domain-specific tokenizers.53 min34Special TokensCovers [CLS], [SEP], [PAD], [MASK], [UNK] tokens, beginning/end of sequence tokens, custom special tokens, special token embeddings, token type IDs, handling special tokens in generation.57 min35Tokenization ChallengesCovers number tokenization issues, code tokenization, multilingual text mixing, emoji and Unicode edge cases, tokenization artifacts, adversarial tokenization, measuring tokenization quality.61 min

Part VI

Sequence Labeling

8 chapters
36Part-of-Speech TaggingCovers POS tag sets (Penn Treebank, Universal), POS tagging as classification, contextual disambiguation, POS tagging accuracy metrics, POS tagging for downstream tasks, rule-based vs statistical taggers.64 min37Named Entity RecognitionCovers entity types (PER, ORG, LOC, etc.), NER as sequence labeling, nested entity challenges, entity boundary detection, NER evaluation (exact vs partial match), NER datasets and benchmarks.60 min38BIO TaggingCovers BIO scheme explanation, BIOES/BILOU variants, converting spans to BIO tags, BIO decoding to spans, handling tagging inconsistencies, BIO for multi-label scenarios, implementing BIO utilities.55 min39ChunkingCovers noun phrase chunking, chunk types (NP, VP, PP), IOB tagging for chunks, chunking vs full parsing, chunking evaluation, chunking as preprocessing, regex chunking with NLTK.41 min40Hidden Markov ModelsCovers HMM components (states, observations, transitions), emission and transition probabilities, HMM assumptions (Markov, independence), HMM for POS tagging, HMM parameter estimation, HMM limitations for NLP.49 min41Viterbi AlgorithmCovers optimal path problem formulation, Viterbi recursion derivation, backpointer tracking, Viterbi complexity analysis, log-space computation, implementing Viterbi efficiently, Viterbi for beam search foundation.47 min42Conditional Random FieldsCovers CRF vs HMM comparison, CRF feature functions, log-linear formulation, partition function computation, CRF for NER, CRF inference complexity, neural CRF layers.58 min43CRF TrainingCovers CRF log-likelihood objective, forward-backward algorithm, gradient computation, L-BFGS optimization, feature template design, CRF regularization, CRF training convergence.56 min
Volume 2 · 25 chapters

Part VII

Linguistic Form: Morphology and Syntax

5 chapters

Part VIII

Semantics and Information Extraction

6 chapters
Volume 3 · 11 chapters

Part X

Neural Network Foundations

13 chapters
61Linear ClassifiersCovers linear decision boundaries, weight vectors and bias, dot product interpretation, multiclass classification (softmax), linear classifier limitations, training with gradient descent.53 min62Activation FunctionsCovers sigmoid function and saturation, tanh properties, ReLU and dying ReLU, Leaky ReLU and PReLU, ELU and SELU, GELU derivation and properties, Swish and Mish, choosing activation functions.50 min63Multilayer PerceptronsCovers hidden layers and depth, weight matrices between layers, forward pass computation, representational capacity, MLP for classification, MLP for regression, MLP architecture design.40 min64Loss FunctionsCovers cross-entropy loss derivation, MSE for regression, binary vs multiclass cross-entropy, label smoothing, focal loss for imbalance, loss function numerical stability, custom loss functions.56 min65BackpropagationCovers computational graphs, chain rule review, forward and backward pass, gradient accumulation, backprop complexity analysis, automatic differentiation, implementing backprop from scratch.58 min66Stochastic Gradient DescentCovers batch vs stochastic gradient descent, minibatch gradient descent, learning rate selection, SGD convergence properties, SGD noise as regularization, learning rate schedules basics, SGD implementation.40 min67MomentumCovers momentum intuition (ball rolling), momentum update equations, momentum coefficient selection, dampening oscillations, momentum vs vanilla SGD, Nesterov momentum derivation, implementing momentum.50 min68Adam OptimizerCovers exponential moving averages, first moment (mean) estimation, second moment (variance) estimation, bias correction derivation, Adam update rule, Adam hyperparameters, Adam convergence properties.51 min69AdamWCovers L2 regularization vs weight decay, why they differ with Adam, AdamW formulation, weight decay coefficient selection, AdamW as default optimizer, AdamW vs Adam empirically.45 min70Weight InitializationCovers random initialization importance, Xavier/Glorot initialization derivation, He initialization for ReLU, initialization for different activations, layer-wise initialization, initialization debugging, modern initialization practices.53 min71Batch NormalizationCovers internal covariate shift, batch statistics computation, learnable scale and shift, training vs inference mode, batch norm gradient flow, batch norm placement debates, batch norm limitations.54 min72DropoutCovers dropout as ensemble, dropout mask sampling, inverted dropout scaling, dropout rate selection, dropout at inference, spatial dropout for sequences, dropout in modern architectures.55 min73Gradient ClippingCovers gradient explosion detection, clip by value, clip by global norm, gradient clipping implementation, when to use gradient clipping, clipping threshold selection, monitoring gradient norms.50 min

Part XI

Recurrent Neural Networks

9 chapters
74RNN ArchitectureCovers recurrent connection intuition, hidden state as memory, unrolled computation graph, parameter sharing across time, RNN for sequence classification, RNN for sequence generation, RNN equations and dimensions.55 min75Backpropagation Through TimeCovers BPTT derivation, gradient flow through time, truncated BPTT, BPTT memory requirements, BPTT implementation, gradient accumulation across timesteps.52 min76Vanishing GradientsCovers gradient product across timesteps, vanishing gradient analysis, long-range dependency failure, gradient visualization, vanishing vs exploding trade-off, architectural solutions overview.45 min77LSTM ArchitectureCovers cell state as information highway, gate mechanism intuition, LSTM diagram walkthrough, information flow in LSTMs, LSTM for long sequences, LSTM memory capacity.55 min78LSTM Gate EquationsCovers forget gate equations, input gate equations, cell state update, output gate equations, hidden state computation, LSTM parameter count, implementing LSTM from scratch.40 min79LSTM Gradient FlowCovers constant error carousel, forget gate gradient highway, gradient flow analysis, LSTM vs vanilla RNN gradients, peephole connections, LSTM gradient clipping needs.52 min80GRU ArchitectureCovers GRU vs LSTM comparison, reset gate function, update gate function, candidate hidden state, GRU equations, GRU parameter efficiency, when to choose GRU vs LSTM.48 min81Bidirectional RNNsCovers forward and backward passes, hidden state concatenation, bidirectional architectures, bidirectionality for classification, limitations for generation, implementing bidirectional RNNs.50 min82Stacked RNNsCovers multiple RNN layers, residual connections for depth, layer normalization in RNNs, depth vs width trade-offs, gradient flow in deep RNNs, practical depth limits.41 min

Part XII

Sequence-to-Sequence

7 chapters
Volume 4 · 29 chapters

Part XIII

Self-Attention

6 chapters

Part XIV

Positional Encoding

7 chapters

Part XV

Transformer Blocks

8 chapters

Part XVI

Transformer Architectures

6 chapters
Volume 5 · 27 chapters

Part XVII

Efficient Attention

9 chapters
117Quadratic Attention BottleneckCovers O(n²) memory analysis, O(n²) compute analysis, attention matrix size, practical sequence limits, bottleneck visualization, motivation for efficiency.48 min118Sparse Attention PatternsCovers local attention windows, strided attention patterns, block-sparse attention, combining sparse patterns, sparse attention implementation.61 min119Sliding Window AttentionCovers sliding window formulation, window size selection, dilated sliding windows, sliding window for long sequences, Mistral-style windowed attention.43 min120Global TokensCovers CLS token global attention, learned global tokens, global-local attention mixing, global token count, implementation strategies.51 min121LongformerCovers Longformer attention pattern, global attention configuration, Longformer complexity, Longformer for documents, Longformer implementation.55 min122BigBirdCovers BigBird attention pattern, random attention benefits, BigBird theoretical guarantees, BigBird vs Longformer, BigBird applications.40 min123Linear AttentionCovers softmax attention reformulation, kernel feature maps, linear complexity attention, linear attention limitations, Performer and variants.42 min124FlashAttention AlgorithmCovers GPU memory hierarchy, tiling for SRAM, online softmax computation, recomputation strategy, FlashAttention complexity, FlashAttention benefits.45 min125FlashAttention ImplementationCovers CUDA kernel basics, memory access patterns, FlashAttention-2 improvements, using FlashAttention in PyTorch, FlashAttention limitations.51 min

Part XVIII

Long Context

7 chapters
Volume 6 · 16 chapters

Part XX

Data Curation

10 chapters

Part XXII

Pre-training Objectives

7 chapters

Part XXIII

Scaling Laws

7 chapters
Volume 7 · 24 chapters

Part XXIV

BERT and Variants

8 chapters

Part XXV

Encoder-Decoder Models

6 chapters
Volume 8 · 14 chapters

Part XXVIII

GPT Architecture

10 chapters
197GPT-1Covers GPT-1 architecture, GPT-1 pre-training, GPT-1 fine-tuning approach, GPT-1 transfer learning, GPT-1 historical significance.68 min198GPT-2Covers GPT-2 model sizes, GPT-2 architectural changes, zero-shot task performance, GPT-2 training data (WebText), GPT-2 generation quality.52 min199GPT-3Covers GPT-3 scale (175B), few-shot prompting discovery, in-context learning analysis, GPT-3 capabilities, GPT-3 limitations.93 min200In-Context LearningCovers ICL phenomenon, ICL vs fine-tuning, example selection strategies, ICL scaling behavior, ICL theoretical understanding.51 min201Autoregressive GenerationCovers generation procedure, KV caching for efficiency, generation stopping criteria, generation speed optimization, generation code implementation.77 min202Decoding TemperatureCovers temperature scaling, temperature effects on distribution, temperature selection guidelines, temperature vs quality trade-off.55 min203Top-k SamplingCovers top-k truncation, k selection strategies, top-k limitations, top-k implementation, combining with temperature.52 min204Nucleus SamplingCovers top-p formulation, cumulative probability threshold, nucleus sampling benefits, p selection guidelines, nucleus vs top-k.42 min205Repetition PenaltiesCovers repetition in generation, repetition penalty formulation, frequency penalty, presence penalty, n-gram blocking.56 min206Constrained DecodingCovers grammar-guided generation, JSON schema constraints, regex constraints, constrained beam search, constrained sampling.41 min

Part XXIX

Modern Decoder Models

7 chapters

Part XXX

Emergent Capabilities

6 chapters
Volume 9 · 23 chapters

Part XXXI

Training Infrastructure

11 chapters

Part XXXII

Training Optimization

8 chapters

Part XXXIII

Mixture of Experts

10 chapters
Volume 10 · 29 chapters

Part XXXIV

Fine-tuning Fundamentals

5 chapters

Part XXXV

Parameter-Efficient Fine-tuning

12 chapters

Part XXXVI

Instruction Tuning

6 chapters
Volume 11 · 23 chapters

Part XXXVII

Alignment and RLHF

16 chapters
272Alignment ProblemCovers alignment definition, helpfulness vs harmlessness, alignment challenges, alignment approaches overview.70 min273Human Preference DataCovers preference collection UI, comparison design, annotator guidelines, preference data quality.67 min274Bradley-Terry ModelCovers pairwise comparison model, preference probability, Bradley-Terry likelihood, preference strength.63 min275Reward ModelingCovers reward model architecture, preference loss function, reward model training, reward model evaluation.68 min276Reward HackingCovers reward hacking examples, distribution shift, over-optimization, reward hacking mitigation.68 min277Policy Gradient MethodsCovers policy definition, REINFORCE algorithm, policy gradient derivation, variance reduction.59 min278PPO AlgorithmCovers clipped objective, PPO derivation, trust region intuition, PPO implementation.71 min279PPO for Language ModelsCovers LLM as policy, action space (tokens), reward assignment, KL penalty importance.64 min280RLHF PipelineCovers SFT stage, reward model training, PPO fine-tuning, RLHF hyperparameters, RLHF debugging.61 min281KL Divergence PenaltyCovers KL penalty motivation, KL coefficient selection, adaptive KL, KL effects on training.69 min282DPO ConceptCovers DPO motivation, removing reward model, DPO intuition, DPO benefits.53 min283DPO DerivationCovers DPO from RLHF objective, optimal policy derivation, DPO loss function, DPO as classification.45 min284DPO ImplementationCovers DPO data format, DPO loss computation, DPO training procedure, DPO hyperparameters.56 min285DPO VariantsCovers IPO formulation, KTO for unpaired feedback, ORPO, cDPO, comparing alignment methods.65 min286RLAIFCovers AI as annotator, constitutional AI principles, AI preference generation, RLAIF scalability.51 min287Iterative AlignmentCovers iterative DPO, online preference learning, self-improvement loops, alignment stability.48 min
Volume 12 · 16 chapters

Part XLI

Model Compression

6 chapters

Part XLII

Inference Optimization

14 chapters
313KV CacheCovers KV cache motivation, cache structure, cache memory requirements, cache management.56 min314KV Cache MemoryCovers cache size calculation, batch size effects, sequence length effects, memory bottleneck.52 min315Paged AttentionCovers memory fragmentation problem, page-based allocation, vLLM approach, paged attention benefits.68 min316KV Cache CompressionCovers cache eviction strategies, attention sink preservation, H2O algorithm, cache quantization.56 min317Weight Quantization BasicsCovers quantization fundamentals, per-tensor vs per-channel, symmetric vs asymmetric, calibration.59 min318INT8 QuantizationCovers INT8 range mapping, absmax quantization, smooth quantization, INT8 accuracy.59 min319INT4 QuantizationCovers 4-bit challenges, group-wise quantization, 4-bit accuracy trade-offs, 4-bit formats.59 min320GPTQCovers GPTQ algorithm, layer-wise quantization, Hessian approximation, GPTQ implementation.49 min321AWQCovers salient weight preservation, AWQ algorithm, AWQ vs GPTQ, AWQ benefits.44 min322GGUF FormatCovers GGML/GGUF history, quantization types, GGUF file format, llama.cpp integration.55 min323Speculative Decoding: Fast LLM Inference Without Quality LossCovers speculative decoding concept, draft model selection, verification procedure, acceptance rate.54 min324Speculative Decoding Math: Algorithms & Speedup LimitsCovers acceptance criterion, expected speedup, draft quality effects, optimal draft length.52 min325Continuous Batching: Optimizing LLM Inference ThroughputCovers static vs continuous batching, iteration-level scheduling, request completion handling, throughput gains.58 min326LLM Inference Serving: Architecture, Routing & Auto-ScalingMaster LLM inference serving architecture, token-aware load balancing, and auto-scaling. Optimize time-to-first-token and throughput for production systems.73 min
Volume 14 · 20 chapters

Part XLIV

Retrieval-Augmented Generation

14 chapters
332RAG Motivation: Solving Hallucinations & Knowledge GapsDiscover why LLMs need Retrieval-Augmented Generation. Learn how RAG bridges knowledge gaps, reduces hallucinations, and enables non-parametric memory.59 min333RAG Architecture: Components, Timing & Design PatternsMaster RAG system design by exploring retriever-generator interactions, timing strategies like iterative retrieval, and architectural variations like RETRO.60 min334Dense Retrieval: Semantic Search & Bi-Encoder ImplementationMaster dense retrieval for semantic search. Explore bi-encoder architectures, embedding metrics, and contrastive learning to overcome keyword limitations.62 min335Contrastive Learning for Retrieval: InfoNCE & DPR GuideMaster contrastive learning for dense retrieval. Learn to train models using InfoNCE loss, in-batch negatives, and hard negative mining strategies effectively.57 min336Document Chunking: Optimizing RAG Retrieval PipelinesMaster document chunking for RAG systems. Explore fixed-size, recursive, and semantic strategies to balance retrieval precision with context window limits.63 min337Embedding Models: Architecture, Pooling & SelectionLearn how embedding models convert text to vectors for RAG. Covers bi-encoder architecture, pooling strategies, dimensionality trade-offs, and model selection.65 min338Vector Similarity Search: Metrics & Approximate MethodsExplore vector similarity search for RAG systems. Compare cosine, dot product, and Euclidean metrics, and implement exact vs. approximate search with FAISS.65 min339HNSW Index: Architecture for Fast Vector SearchMaster Hierarchical Navigable Small World (HNSW) graphs for vector search. Learn graph architecture, construction, and tuning for high-speed retrieval.67 min340IVF Index: Clustering-Based Vector Search & PartitioningMaster IVF indexes for scalable vector search. Learn clustering-based partitioning, nprobe tuning, and IVF-PQ compression for billion-scale retrieval.66 min341Product Quantization: Vector Compression for ANN SearchLearn how Product Quantization compresses embeddings up to 100x using learned codebooks and asymmetric distance computation for scalable vector search.62 min342Hybrid Search: BM25 and Dense Retrieval CombinedLearn how hybrid search fuses BM25 keyword retrieval with dense vector retrieval using reciprocal rank fusion and weighted score combination to improve recall.65 min343Reranking: Cross-Encoders for Precise Information RetrievalLearn how reranking with cross-encoders solves bi-encoder limitations. Master two-stage retrieval, training strategies, and latency optimization for production search systems.61 min344RAG Prompt Engineering: Context Placement & Citation StrategiesMaster RAG prompt engineering with strategic context placement, citation formats, and truncation strategies to improve LLM accuracy and reduce hallucinations.53 min345RAG Evaluation: Metrics for Retrieval and Generation QualityMaster RAG evaluation with metrics for retrieval quality (Precision@K, NDCG, MRR) and generation faithfulness using the RAGAS framework for AI systems.65 min

Part XLVI

Continual Learning

5 chapters
Volume 15 · 19 chapters

Part XLVII

Code Generation

6 chapters

Part XLVIII

Tool Use and Agents

10 chapters
363Tool Use Motivation: Why LLMs Need External Tools for AccuracyDiscover why LLMs require external tools to overcome knowledge cutoffs, computational limits, and hallucinations. Learn about tool-augmented AI systems.57 min364Function Calling: Structured Tool Use for Large Language ModelsLearn how function calling enables LLMs to invoke external tools and APIs through structured JSON schemas, bridging natural language and executable code.56 min365ReAct Pattern: Interleaving Reasoning and Action for LLM AgentsLearn how the ReAct pattern enables LLM agents to interleave reasoning with tool execution. Master thought-action-observation loops for autonomous AI systems.50 min366Tool Selection for LLM Agents: Routing Strategies and ImplementationMaster LLM tool selection through embedding-based routing, hybrid strategies, and semantic interfaces. Learn to build scalable multi-tool agent systems.58 min367Agent Architectures: Control Loops, State & PlanningMaster LLM agent architectures including control loops, state management strategies, planning mechanisms, and termination conditions for autonomous AI systems.53 min368Agent Memory Systems: From Context to Persistent StorageLearn how AI agents manage short-term context and long-term memory. Explore vector databases, retrieval algorithms, and memory hierarchies that enable persistent, learning systems.52 min369Agent Evaluation: Metrics, Benchmarks and Safety StandardsLearn to evaluate AI agents with task completion metrics, trajectory analysis, and safety testing. Covers WebArena, SWE-bench, GAIA, and OSWorld benchmarks.52 min370PlanningCovers task decomposition, goal-directed planning, plan execution, plan revision and recovery.61 min371Multi-Agent SystemsCovers agent coordination, communication protocols, role assignment, multi-agent benchmarks.55 min372Agent SafetyCovers unsafe action prevention, agent alignment, sandboxing, monitoring and intervention.55 min
Volume 16 · 16 chapters

Part L

Multimodal Models

12 chapters

Part LI

Speech and Audio

5 chapters
Volume 17 · 17 chapters

Part LIII

Evaluation Fundamentals

10 chapters

Part LIV

Benchmark Evaluation

8 chapters

Part LV

Human and Model Evaluation

6 chapters

Part LVI

Hallucination and Factuality

6 chapters
Volume 18 · 30 chapters

Part LVIII

Bias and Fairness

5 chapters

Part LIX

Interpretability

11 chapters
446Interpretability GoalsCovers debugging, trust, safety, scientific understanding, interpretability approaches overview.46 min447Attention VisualizationCovers attention weight extraction, attention head visualization, attention interpretation caveats, attention tools.51 min448Attention Analysis LimitationsCovers attention vs importance, attention manipulation studies, gradient-based alternatives.47 min449Probing ClassifiersCovers linear probing methodology, probing task design, probing interpretation, control tasks.52 min450Probing LayersCovers layer selection, representation evolution, task localization, layer probing patterns.55 min451Activation PatchingCovers patching methodology, locating information, patching experiments, causal tracing.49 min452Logit LensCovers logit lens concept, intermediate vocabulary projection, tuned lens, lens interpretation.45 min453Sparse AutoencodersCovers SAE architecture, sparsity constraints, dictionary learning, SAE for LLMs.59 min454Feature InterpretationCovers feature activation patterns, feature naming, automated interpretation, feature circuits.57 min455Mechanistic InterpretabilityReverse-engineer transformer networks into human-understandable algorithms by identifying circuits, induction heads, and mechanistic discoveries.52 min456Activation Steering: Steering Vectors and Representation EngineeringLearn how steering vectors and activation addition let you modify language model behavior at inference time by injecting directional nudges into the residual stream.47 min

Part LX

Safety and Security

8 chapters
Volume 19 · 24 chapters

Part LXIII

LLM Applications

7 chapters

Part LXV

Production Systems

9 chapters
Volume 20 · 16 chapters

Part LXVI

Frontier Methods of 2025

8 chapters

Part LXVII

Frontier Outlook from 2025

6 chapters
Appendix · 14 chapters

More about the book

Begin with the fundamentals that never go out of style: tokenization, embeddings, and the statistical foundations that inform modern approaches. Then dive deep into the transformer architecture. Learn not just how to use it, but how it actually works. Understand self-attention mathematically, grasp why positional encodings matter, and see how architectural choices like layer normalization affect training dynamics.

The landscape of pretrained models can be overwhelming. BERT, GPT, T5, LLaMA, Claude: what are the real differences? When should you use an encoder versus a decoder? How do you actually fine-tune a model for your use case? This handbook cuts through the confusion with clear explanations of each architecture family, their strengths and weaknesses, and practical guidance on selection and adaptation.

From retrieval-augmented generation to RLHF alignment, from efficient inference to safety considerations, every topic a modern NLP practitioner needs is covered with the depth that lets you actually apply it. Whether you're building production systems, conducting research, or simply want to truly understand the technology reshaping our world, this is your comprehensive guide to language AI.

Own the library

The whole growing library, yours forever.

Reading online is free, and always will be. The paid library unlocks every current volume as its own carefully typeset PDF, plus each future volume when it is published. There is intentionally no combined PDF.
  • All 393 written chapters across 19 available volumes

  • 19 written volume PDFs plus the Volume 3 placeholder. Files are delivered separately.

  • All future expansions, updates, and errata, free, forever

  • Every future volume included, including 95 planned chapters

  • Downloadable editions for durable offline reading

Best value, save $257 (56%)

$199

one-time

instead of $456 for the 19 available volume PDFs bought separately

Language AI Handbook Cover
5.0 from 12 readers

Secure checkout via Stripe · Individual PDF links delivered to your inbox

Reader verdict

5.0

out of 5

12 five-star reader reviews

Genuine feedback, with names abbreviated for privacy.

Meet the community
“Really appreciate the way you have explained the concepts. Simple to understand, yet builds up knowledge exponentially, all while reinforcing it with examples repeatedly. I've read the last two chapters `74.Self-attention & 75.Q,K,V` and I've to admit, my concepts have never been clearer. You really are doing an amazing job breaking down maths and complex concepts like a story!”
Muhammad H.AI/ML Engineer
“I would like to thank you for your work. Specifically, the chapter: 'LIME Explainability: Complete Guide to Local Interpretable Model-Agnostic Explanations' was extremely helpful for me in understanding LIME and communicating to colleagues. Your work is inspiring and valuable. Thank you for doing it.”
Will G.Data Scientist
“I am enjoying reading your writings. I appreciate the effort you put into it. I want to drop a note of thanks. Thank you!”
Krishnan S.Researcher
“Your writing feels like a treasure trove of great material. So, thank you for compiling everything on your website!”
Griffin P.Quantitative Researcher
“I found your book Language AI Handbook's explanations of Transformer architectures and production deployment strategies to be exceptionally clear and insightful”
San Z.Researcher
“Thanks so much for establishing such an amazing community. I appreciate the opportunity to be a learner and a contributor to the community.”
Cyrille L.AI/ML Engineer
“Thank you Michael. It's top!”
David X.Data Scientist
“I came across your collection of online handbooks covering quantitative finance, AI, and machine learning. I wanted to reach out and thank you for making such high-quality material openly available. They are incredibly helpful for my CFA Level II review and for brushing up ahead of ML interviews.”
Karim Z.Reader
“I came across one of your books, Language AI Handbook, and man, I'm loving it. I've read many books but have never found such a comprehensive book on large models that covers everything from start to finish with such depth.”
Uon L.Reader
“I just came across your website where your books are available for free to read. Thank you so much for making this available to the public. This will help a lot of people.”
Vikas C.AI/ML Engineer
“Thanks for putting cool stuff out into the world.”
Charlie B.Applied AI
“I read a few of your blogs on NLP and oh WOW, they really are something, now I exactly know how all of the terms Entropy, Cross-entropy and how it is connected to Perplexity, will definitely read more of your blogs.”
Kanishk K.Reader
Read all 12 reader reviews
“I would like to thank you for your work. Specifically, the chapter: 'LIME Explainability: Complete Guide to Local Interpretable Model-Agnostic Explanations' was extremely helpful for me in understanding LIME and communicating to colleagues. Your work is inspiring and valuable. Thank you for doing it.”
Will G.Data Scientist
“Really appreciate the way you have explained the concepts. Simple to understand, yet builds up knowledge exponentially, all while reinforcing it with examples repeatedly. I've read the last two chapters `74.Self-attention & 75.Q,K,V` and I've to admit, my concepts have never been clearer. You really are doing an amazing job breaking down maths and complex concepts like a story!”
Muhammad H.AI/ML Engineer
“Thanks so much for establishing such an amazing community. I appreciate the opportunity to be a learner and a contributor to the community.”
Cyrille L.AI/ML Engineer
“I just came across your website where your books are available for free to read. Thank you so much for making this available to the public. This will help a lot of people.”
Vikas C.AI/ML Engineer
“I am enjoying reading your writings. I appreciate the effort you put into it. I want to drop a note of thanks. Thank you!”
Krishnan S.Researcher
“Thank you Michael. It's top!”
David X.Data Scientist
“Thanks for putting cool stuff out into the world.”
Charlie B.Applied AI
“I found your book Language AI Handbook's explanations of Transformer architectures and production deployment strategies to be exceptionally clear and insightful”
San Z.Researcher
“Your writing feels like a treasure trove of great material. So, thank you for compiling everything on your website!”
Griffin P.Quantitative Researcher
“I came across your collection of online handbooks covering quantitative finance, AI, and machine learning. I wanted to reach out and thank you for making such high-quality material openly available. They are incredibly helpful for my CFA Level II review and for brushing up ahead of ML interviews.”
Karim Z.Reader
“I read a few of your blogs on NLP and oh WOW, they really are something, now I exactly know how all of the terms Entropy, Cross-entropy and how it is connected to Perplexity, will definitely read more of your blogs.”
Kanishk K.Reader
“I came across one of your books, Language AI Handbook, and man, I'm loving it. I've read many books but have never found such a comprehensive book on large models that covers everything from start to finish with such depth.”
Uon L.Reader

Author and edition details

About the author and this edition
Michael Brenndoerfer, author of Language AI Handbook

Michael Brenndoerfer

Michael has spent more than a decade working across software engineering, data, AI, and business. He writes to understand difficult ideas more deeply and to share what he learns in a clear, practical way.

Edition
First edition
Published
Last reviewed

Version history

Kept current, not frozen in time

Library access includes every future volume and update. When a volume changes, its updated PDF appears in My books at no extra cost.

Current release

Edition 2026.08.0

Initial volume-library release with 19 written PDFs, a Volume 3 placeholder, and no combined edition.

Cite this book

Reference

Citation details

Cite or share this article.

BIBTEXAcademic
@book{brenndoerfer2025languageaihandbook, author = {Michael Brenndoerfer}, title = {Language AI Handbook}, year = {2025}, url = {https://mbrenndoerfer.com/books/language-ai-handbook}, publisher = {mbrenndoerfer.com}, note = {Accessed: 2026-11-13} }
APAAcademic
Michael Brenndoerfer (2025). Language AI Handbook. Retrieved from https://mbrenndoerfer.com/books/language-ai-handbook
MLAAcademic
Michael Brenndoerfer. "Language AI Handbook." 2026. Web. November 13, 2026. <https://mbrenndoerfer.com/books/language-ai-handbook>.
CHICAGOAcademic
Michael Brenndoerfer. "Language AI Handbook." Accessed November 13, 2026. https://mbrenndoerfer.com/books/language-ai-handbook.
HARVARDAcademic
Michael Brenndoerfer (2025) 'Language AI Handbook'. Available at: https://mbrenndoerfer.com/books/language-ai-handbook (Accessed: November 13, 2026).
SimpleBasic
Michael Brenndoerfer (2025). Language AI Handbook. https://mbrenndoerfer.com/books/language-ai-handbook