Volume 9 of 20 · PDF edition
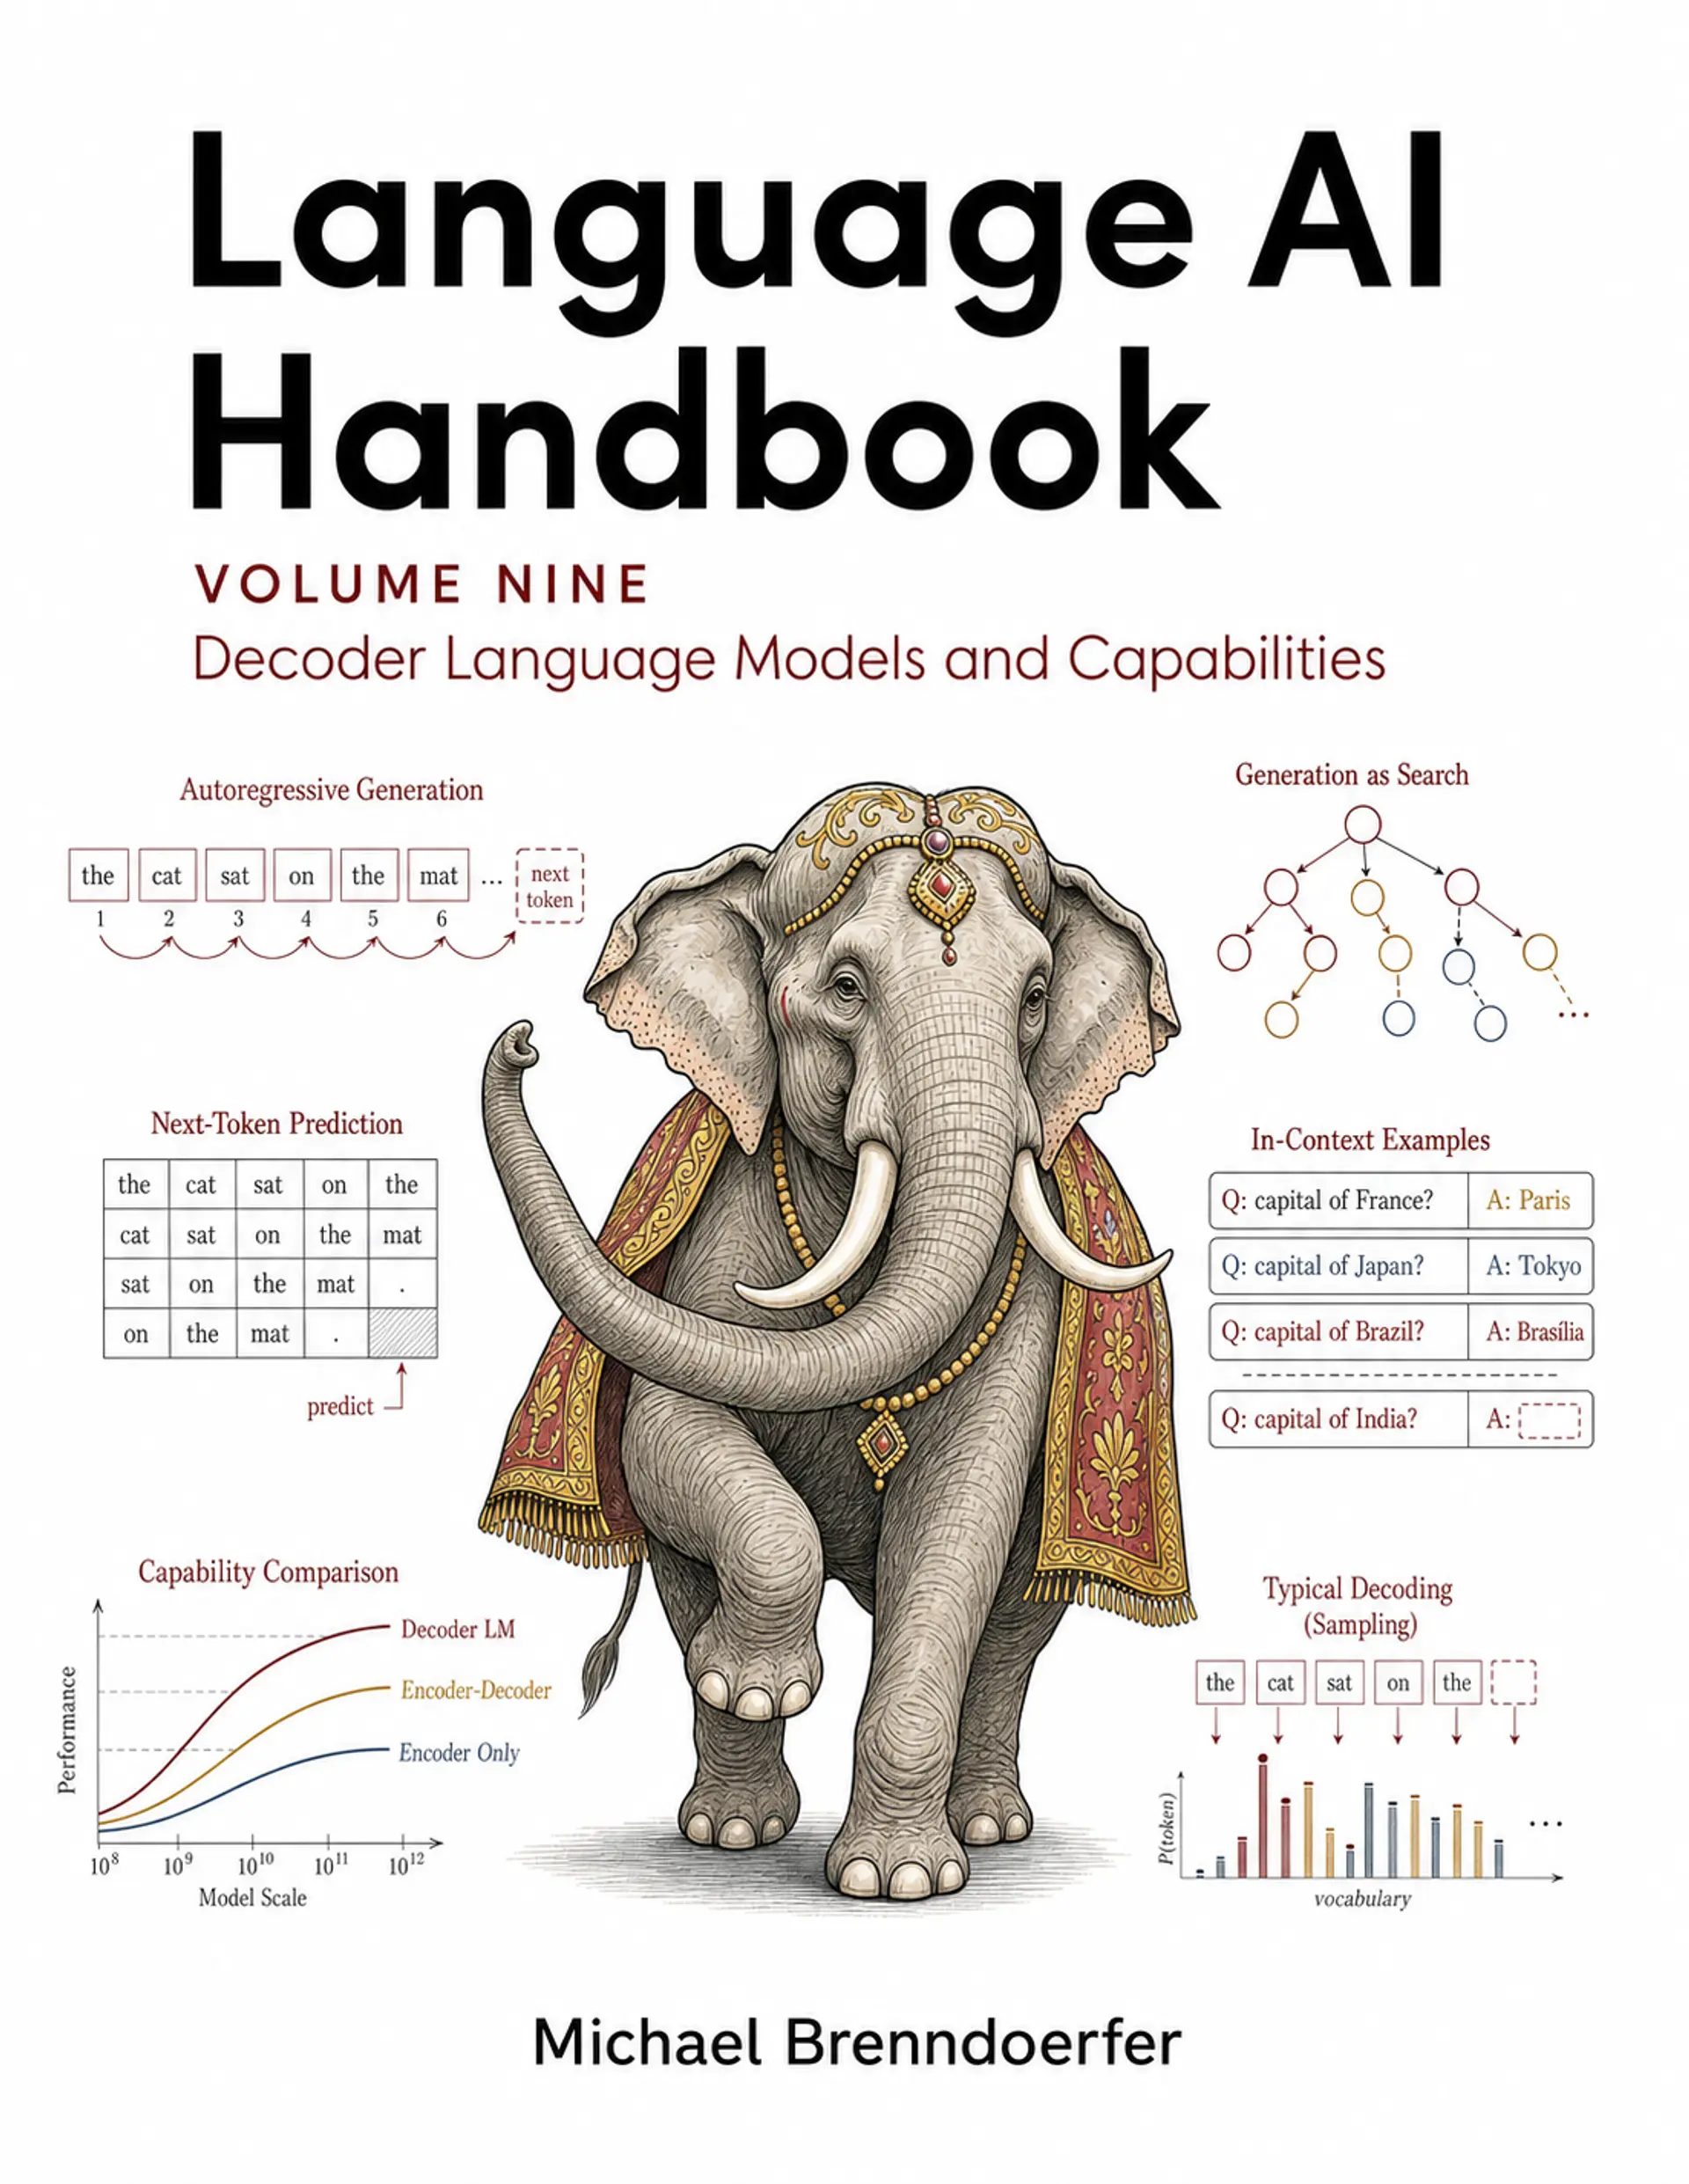
Available nowDecoder Language Models and Capabilities
For readers who want to understand GPT-style generation, modern open decoder families, in-context learning, and capability claims.
Read every available chapter online for free. The paid edition is a focused, carefully typeset volume PDF with future chapters, updates, and errata included.
- Written chapters
- 23 written chapters
- Approximate pages
- ~730 pages
- Edition
- Version 2026.08.0
- Price
- $24 one-time
Author and edition details
About the author and Volume 9 PDF edition
Michael Brenndoerfer
Michael has spent more than a decade working across software engineering, data, AI, and business. He writes to understand difficult ideas more deeply and to share what he learns in a clear, practical way.
- Edition
- Volume 9 PDF 2026.08.0
- Published
- Last reviewed
Focused learning path
What this volume covers
- GPT Architecture
- Modern Decoder Models
- Emergent Capabilities
Audience and prerequisites
Where this volume fits
For readers who want to understand GPT-style generation, modern open decoder families, in-context learning, and capability claims.
Prerequisites: Assumes Volume 5 and the pre-training concepts in Volume 7.
Free online preview
Start with “GPT-1”
Covers GPT-1 architecture, GPT-1 pre-training, GPT-1 fine-tuning approach, GPT-1 transfer learning, GPT-1 historical significance.
Exact contents
23 chapters available now
Part XXVIII: GPT Architecture
- 01GPT-1
Covers GPT-1 architecture, GPT-1 pre-training, GPT-1 fine-tuning approach, GPT-1 transfer learning, GPT-1 historical significance.
- 02GPT-2
Covers GPT-2 model sizes, GPT-2 architectural changes, zero-shot task performance, GPT-2 training data (WebText), GPT-2 generation quality.
- 03GPT-3
Covers GPT-3 scale (175B), few-shot prompting discovery, in-context learning analysis, GPT-3 capabilities, GPT-3 limitations.
- 04In-Context Learning
Covers ICL phenomenon, ICL vs fine-tuning, example selection strategies, ICL scaling behavior, ICL theoretical understanding.
- 05Autoregressive Generation
Covers generation procedure, KV caching for efficiency, generation stopping criteria, generation speed optimization, generation code implementation.
- 06Decoding Temperature
Covers temperature scaling, temperature effects on distribution, temperature selection guidelines, temperature vs quality trade-off.
- 07Top-k Sampling
Covers top-k truncation, k selection strategies, top-k limitations, top-k implementation, combining with temperature.
- 08Nucleus Sampling
Covers top-p formulation, cumulative probability threshold, nucleus sampling benefits, p selection guidelines, nucleus vs top-k.
- 09Repetition Penalties
Covers repetition in generation, repetition penalty formulation, frequency penalty, presence penalty, n-gram blocking.
- 10Constrained Decoding
Covers grammar-guided generation, JSON schema constraints, regex constraints, constrained beam search, constrained sampling.
Part XXIX: Modern Decoder Models
- 01LLaMA Architecture
Covers LLaMA design philosophy, LLaMA architectural choices, LLaMA training data, LLaMA efficiency, LLaMA significance.
- 02LLaMA Components
Covers pre-norm with RMSNorm, SwiGLU FFN, RoPE implementation, component interactions, implementation details.
- 03Grouped Query Attention
Covers GQA motivation, GQA formulation, KV head grouping, GQA memory savings, GQA vs MHA performance, GQA implementation.
- 04Multi-Query Attention
Covers MQA extreme sharing, MQA memory benefits, MQA quality trade-offs, MQA for inference, MQA vs GQA.
- 05Mistral Architecture
Covers Mistral design choices, sliding window attention, Mistral efficiency, Mistral performance, Mistral vs LLaMA.
- 06Qwen Architecture
Covers Qwen architectural choices, Qwen training approach, Qwen multilingual capabilities, Qwen variants.
- 07Phi Models
Covers Phi design philosophy, textbook-quality data, Phi training approach, Phi efficiency, small model capabilities.
Part XXX: Emergent Capabilities
- 01Emergence in Neural Networks
Covers emergence definition, phase transitions, emergence examples, emergence mechanisms, emergence debate.
- 02In-Context Learning Emergence
Covers ICL emergence curves, ICL vs fine-tuning scaling, ICL mechanism hypotheses, ICL as meta-learning.
- 03Chain-of-Thought Emergence
Covers CoT emergence observations, CoT elicitation, CoT scaling behavior, CoT mechanism theories.
- 04Emergence vs Metrics
Covers discontinuous metrics, accuracy threshold effects, smooth underlying capabilities, re-examining emergence claims.
- 05Inverse Scaling
Covers inverse scaling phenomena, distractor tasks, sycophancy scaling, inverse scaling prize findings.
- 06Grokking
Covers grokking phenomenon, grokking in arithmetic, grokking mechanism theories, grokking phase transitions, practical implications.
Volume 9 PDF
Own this focused edition
Get the carefully typeset PDF to keep, plus every future chapter, revision, and erratum for this volume.
- Carefully typeset standalone volume PDF
- Future chapters, updates, and errata included
- No oversized combined edition to render or download
Volume 9 of 20
$24
one-timeVersion 2026.08.0 · secure checkout via Stripe
Delivered by email · Free volume updates included
All-volume access
Every current and future volume
Get all 20 current volume slots, every future volume, and every update for $199. PDFs are always delivered as manageable individual volumes, never as one combined 12,500-page file.
$199 one-time
Get all-volume accessContinue through the library
Explore adjacent volumes
Version history
Kept current, not frozen in time
Each PDF purchase includes future editions. When the book changes, the updated copy appears in My books at no extra cost.
Current release
Edition 2026.08.0
Initial volume-library release with 19 written PDFs, a Volume 3 placeholder, and no combined edition.